GPT 6 Astra pricing
GPT-6 Astra API pricing in USD: input, output, two cache-write durations, long-context rates and worked budgets, with checked reAPI prices and clear limits.
GPT-6 Astra pricing on OpenAI's Standard API starts at $10 per million uncached input tokens and $50 per million output tokens, for prompts of up to 272,000 input tokens. Cached reads cost $1 per million; cache writes cost $12.50 for the 30-minute option or $25 for the 12-hour option. Above the input threshold, the entire request uses higher rates[1].
The reAPI GPT-6 Astra page displayed $8 input and $40 output per million tokens in the shorter-prompt tier when checked on October 23, 2026[2]. This guide separates the two providers' published rates, works through request budgets, and explains why a subscription price or a single input-token number cannot tell you what an API workload will cost.
- Count output, including reasoning. A longer reasoning pass increases billed output even when the final visible answer is short[3].
- Check each request's input length. OpenAI changes the full request's rates above 272,000 input tokens; this is not a monthly usage threshold[4].
- Keep cache writes separate from reads. OpenAI's 30-minute and 12-hour writes have different rates. The reAPI price display does not label a retention duration[1][2].
- Compare equivalent service tiers. OpenAI Batch and Flex rates are half Standard, so a lower reAPI Standard-style rate does not make it the cheapest option for every job[1].
gpt 6 astra token pricing
All prices below are USD per 1,000,000 tokens, checked October 23, 2026. The OpenAI columns use Standard processing. The reAPI columns reproduce the model page's displayed rates; they do not claim support for every OpenAI processing tier or cache control[1][2].
| Billing category | OpenAI, input ≤272K | OpenAI, input >272K | reAPI, input ≤272K | reAPI, input >272K |
|---|---|---|---|---|
| Uncached input | $10.00 | $20.00 | $8.00 | $16.00 |
| Cached input read | $1.00 | $2.00 | $0.80 | $1.60 |
| Cache write, 30 minutes | $12.50 | $25.00 | — | — |
| Cache write, 12 hours | $25.00 | $50.00 | — | — |
| Cache write, duration unspecified on price display | — | — | $10.00 | $20.00 |
| Output, including reasoning | $50.00 | $75.00 | $40.00 | $60.00 |
A dash means that the table does not establish an equivalent offering. It does not mean free. In particular, the displayed $10 reAPI write rate cannot be called a 12-hour cache price. Its lower number alone does not establish the same retention behavior.
OpenAI's cache-write categories replace the ordinary input charge for those tokens. Do not charge a written token once as ordinary input and again as a cache write. Its caching guide separates total input into ordinary input, cached reads and the two write categories. The explicit TTL control is available through Responses; a 12-hour retention setting establishes a minimum retention period, not a promise to delete the cached prefix at that moment[5].
OpenAI also publishes these shorter-prompt processing rates[1]:
| OpenAI tier, input ≤272K | Input | Cache read | 30-minute write | 12-hour write | Output |
|---|---|---|---|---|---|
| Standard | $10.00 | $1.00 | $12.50 | $25.00 | $50.00 |
| Batch | $5.00 | $0.50 | $6.25 | $12.50 | $25.00 |
| Flex | $5.00 | $0.50 | $6.25 | $12.50 | $25.00 |
| Fast | $20.00 | $2.00 | $25.00 | $50.00 | $100.00 |
| Ultrafast | $60.00 | $6.00 | $75.00 | $150.00 | $300.00 |
Batch is asynchronous, with a 24-hour completion window; Flex trades lower prices for slower responses and occasional resource unavailability[6][7]. These are price options, not a claim that every account, region or endpoint can select each one. Above 272K input tokens, apply the corresponding long-context rates. The reAPI API documentation describes Chat Completions at https://reapi.ai/api/v1/chat/completions; it does not offer a public Responses or Batch endpoint. Do not assume that setting an OpenAI-specific tier or cache field on that endpoint purchases the corresponding OpenAI service[8].
gpt 6 astra cost per task
The useful budget starts with the tokens in each billing category. For OpenAI Standard, using counts from a request in the appropriate context tier:
cost = (ordinary_input × input_rate
      + cache_reads × read_rate
      + cache_writes_30m × write_30m_rate
      + cache_writes_12h × write_12h_rate
      + billed_output × output_rate) / 1,000,000
Add separately billed tools or other applicable charges. For another provider, use its documented categories rather than assuming these TTL controls transfer. All examples here are illustrative arithmetic, not measured traffic or performance tests. They exclude tool charges and assume the stated service tier.
A small uncached request. Take 2,000 input tokens and 800 total billed output tokens, including any reasoning. The OpenAI Standard calculation is 2,000 × $10 / 1M + 800 × $50 / 1M = $0.06. Using the observed reAPI rates gives 2,000 × $8 / 1M + 800 × $40 / 1M = $0.048. For 1,000 such requests, that is $60 versus $48: a 20% reduction for this exact workload.
If those same token counts qualify for OpenAI Batch pricing, the input and output bill is $0.03 per request, or $30 for 1,000. That is lower than the $48 reAPI total. Whether the job can use Batch is a separate workflow decision; the two prices are not interchangeable latency promises.
An output-heavy request. Now keep the input at 2,000 tokens but use 8,000 billed output tokens. OpenAI Standard costs $0.02 + $0.40 = $0.42; the observed reAPI rates produce $0.016 + $0.32 = $0.336. Input length alone misses most of this bill. For reasoning models, use the billed output count rather than counting only the text that a person reads[3].
A repeated reference document. Suppose 20 calls use the same 50,000-token prefix, add 2,000 fresh input tokens each, and produce 1,000 billed output tokens each. Assume the first call writes the prefix once using OpenAI's 30-minute option, all later calls hit that prefix, and the fresh input is billed as ordinary input. Every prompt remains below 272K.
| Component | Calculation at OpenAI Standard rates | USD |
|---|---|---|
| Initial prefix write | 50,000 × $12.50 / 1M | $0.625 |
| 19 prefix reads | 19 × 50,000 × $1 / 1M | $0.950 |
| Fresh input | 20 × 2,000 × $10 / 1M | $0.400 |
| Output | 20 × 1,000 × $50 / 1M | $1.000 |
| Total with the assumed cache hits | $2.975 | |
| Same token counts, all input uncached | 20 × 52,000 × $10 / 1M + $1 | $11.400 |
Changing only that first write to the 12-hour option makes it $1.250 and the total $3.600. The longer option buys a different retention condition; it is not a second write charge on top of the first. If calls miss the cache or create new prefixes, those assumptions no longer describe the bill. Do not advertise the calculated saving as a guaranteed discount for every application.
gpt 6 astra context window
GPT-6 Astra's documented context window is 1,050,000 tokens, with a maximum of 922,000 input tokens and 128,000 output tokens. The cheaper pricing tier ends well before the maximum input limit[4].
OpenAI doubles input and cache rates and multiplies output rates by 1.5 when input exceeds 272,000 tokens, for the whole request. Cached input remains part of the prompt; a large cached prefix does not make a large request short-context for billing purposes[1][5].
For an uncached 270,000-token input and 5,000-token output, OpenAI Standard costs 270,000 × $10 / 1M + 5,000 × $50 / 1M = $2.95. At 300,000 input tokens, it becomes 300,000 × $20 / 1M + 5,000 × $75 / 1M = $6.375. The respective reAPI calculations, using its displayed tiers, are $2.36 and $5.10. The higher rate does not apply only to the final 28,000 tokens above the threshold.
This is why a monthly estimate should group requests by prompt length before adding them up. A monthly input total cannot reveal how many individual requests crossed the threshold. Cutting context is useful only if the remaining material still lets the model do the job; a cheaper failed answer is not a successful cost reduction.
gpt 6 astra pricing vs sol
Here are the shorter-prompt Standard rates on OpenAI's price page, checked October 23, 2026[1]:
| Model | Input | Cache read | 30-minute write | 12-hour write | Output |
|---|---|---|---|---|---|
| GPT-6 Astra | $10.00 | $1.00 | $12.50 | $25.00 | $50.00 |
| GPT-6 Sol | $2.00 | $0.20 | $2.50 | $5.00 | $10.00 |
| GPT-6 Luna | $0.10 | $0.01 | $0.125 | $0.25 | $0.50 |
For identical token categories and counts, Sol costs one fifth of Astra and Luna one hundredth. That arithmetic does not establish equal accuracy, token usage or completion rates. Use the GPT-6 Sol vs Astra comparison for the model-choice question, and GPT-6 Sol pricing for its own worked budgets.
The corresponding reAPI model pages displayed the following shorter-prompt rates on October 23, 2026. Their cache-write rows do not identify a duration[2][9][10]:
| Model on reAPI | Input | Cache read | Cache write, duration unspecified | Output |
|---|---|---|---|---|
| GPT-6 Astra | $8.00 | $0.80 | $10.00 | $40.00 |
| GPT-6 Sol | $1.600 | $0.016 | $2.000 | $8.000 |
| GPT-6 Luna | $0.080 | $0.008 | $0.100 | $0.400 |
The Sol cache-read number is the displayed $0.016, not a value inferred by multiplying the official price by a uniform discount. Compare each billing category rather than applying a single platform-wide percentage.
Protocol requirements also affect the purchase. OpenAI's Astra tool calling requires Responses; reAPI's Astra documentation does not promise it on Chat Completions[8]. A lower token rate on an endpoint that lacks the required tool surface is not a substitute for the needed integration.
gpt 6 astra pricing subscription
An API token budget is a different purchase from access to GPT-6 Astra inside ChatGPT. The rates above describe metered API requests. They should not be multiplied into, or presented as, a ChatGPT Plus or Pro subscription allowance. For the product-access question, see who gets GPT-6 Astra; this article does not reproduce a subscription price as an API price[11].
If you use several clients, identify which account actually pays for each request. The reAPI documentation requires a reAPI API key and bills from the reAPI credit balance[8]. A subscription shown in a different product is not evidence of a balance in that account.
gpt 6 astra price in india
The official API price table checked for this article quotes USD per million tokens. We did not find a separate India-specific GPT-6 Astra API rate in that table[1]. Use the USD figures above when estimating the API workload. An INR figure would need its own dated exchange-rate and payment assumptions; we have not invented a local price or treated a ChatGPT subscription in rupees as an API tariff.
This pricing answer does not establish a particular account's eligibility or supported payment method. Check those separately before purchasing. For GPT-6 Astra pricing, the practical starting point is the same: choose the endpoint and billing categories, estimate billed output, then separate requests that cross 272K input tokens.
How much does chat gpt-6 astra cost?
For the API, OpenAI Standard starts at $10 input and $50 output per million tokens up to 272K input, with separate cache rates. The observed reAPI input/output rates were $8 and $40 in that tier. Those are API usage rates, not a ChatGPT subscription fee[1][2].
Will GPT-6 Astra be free?
The API tables checked here list paid per-token rates. They do not establish a free, unlimited Astra API allowance, and this guide makes no prediction about future offers. The cost examples assume paid usage; check any promotion's own eligibility, duration and usage restrictions before including it in a budget.
References
- OpenAI. API pricing. Checked October 23, 2026. developers.openai.com/api/docs/pricing
- reAPI. GPT-6 Astra rendered pricing table. Checked October 23, 2026. reapi.ai/models/gpt-6-astra
- OpenAI. Reasoning models. Checked October 23, 2026. developers.openai.com/api/docs/guides/reasoning
- OpenAI. GPT-6 Astra model reference. Checked October 23, 2026. developers.openai.com/api/docs/models/gpt-6-astra
- OpenAI. Prompt caching. Checked October 23, 2026. developers.openai.com/api/docs/guides/prompt-caching
- OpenAI. Batch API. Checked October 23, 2026. developers.openai.com/api/docs/guides/batch
- OpenAI. Flex processing. Checked October 23, 2026. developers.openai.com/api/docs/guides/flex-processing
- reAPI. GPT-6 Astra API documentation; public route surface checked against the local implementation. Checked October 23, 2026. reapi.ai/docs/gpt-6-astra
- reAPI. GPT-6 Sol rendered pricing table. Checked October 23, 2026. reapi.ai/models/gpt-6-sol
- reAPI. GPT-6 Luna rendered pricing table. Checked October 23, 2026. reapi.ai/models/gpt-6-luna
- OpenAI. Codex pricing: subscription usage and API token prices. Checked October 23, 2026. learn.chatgpt.com/docs/pricing
More Posts
Background Removal API Pricing: Cost per Usable Image
Calculate background removal API pricing from a live 88-credit rate, then add rejected outputs, retries, storage, and review to find your usable-image cost.


Best-Value Seedance 2.0 API in 2026: Prices Compared
A matched Seedance 2.0 API price comparison across reAPI, Atlas, Replicate, fal, and WaveSpeed, including billing rules and best-value picks.
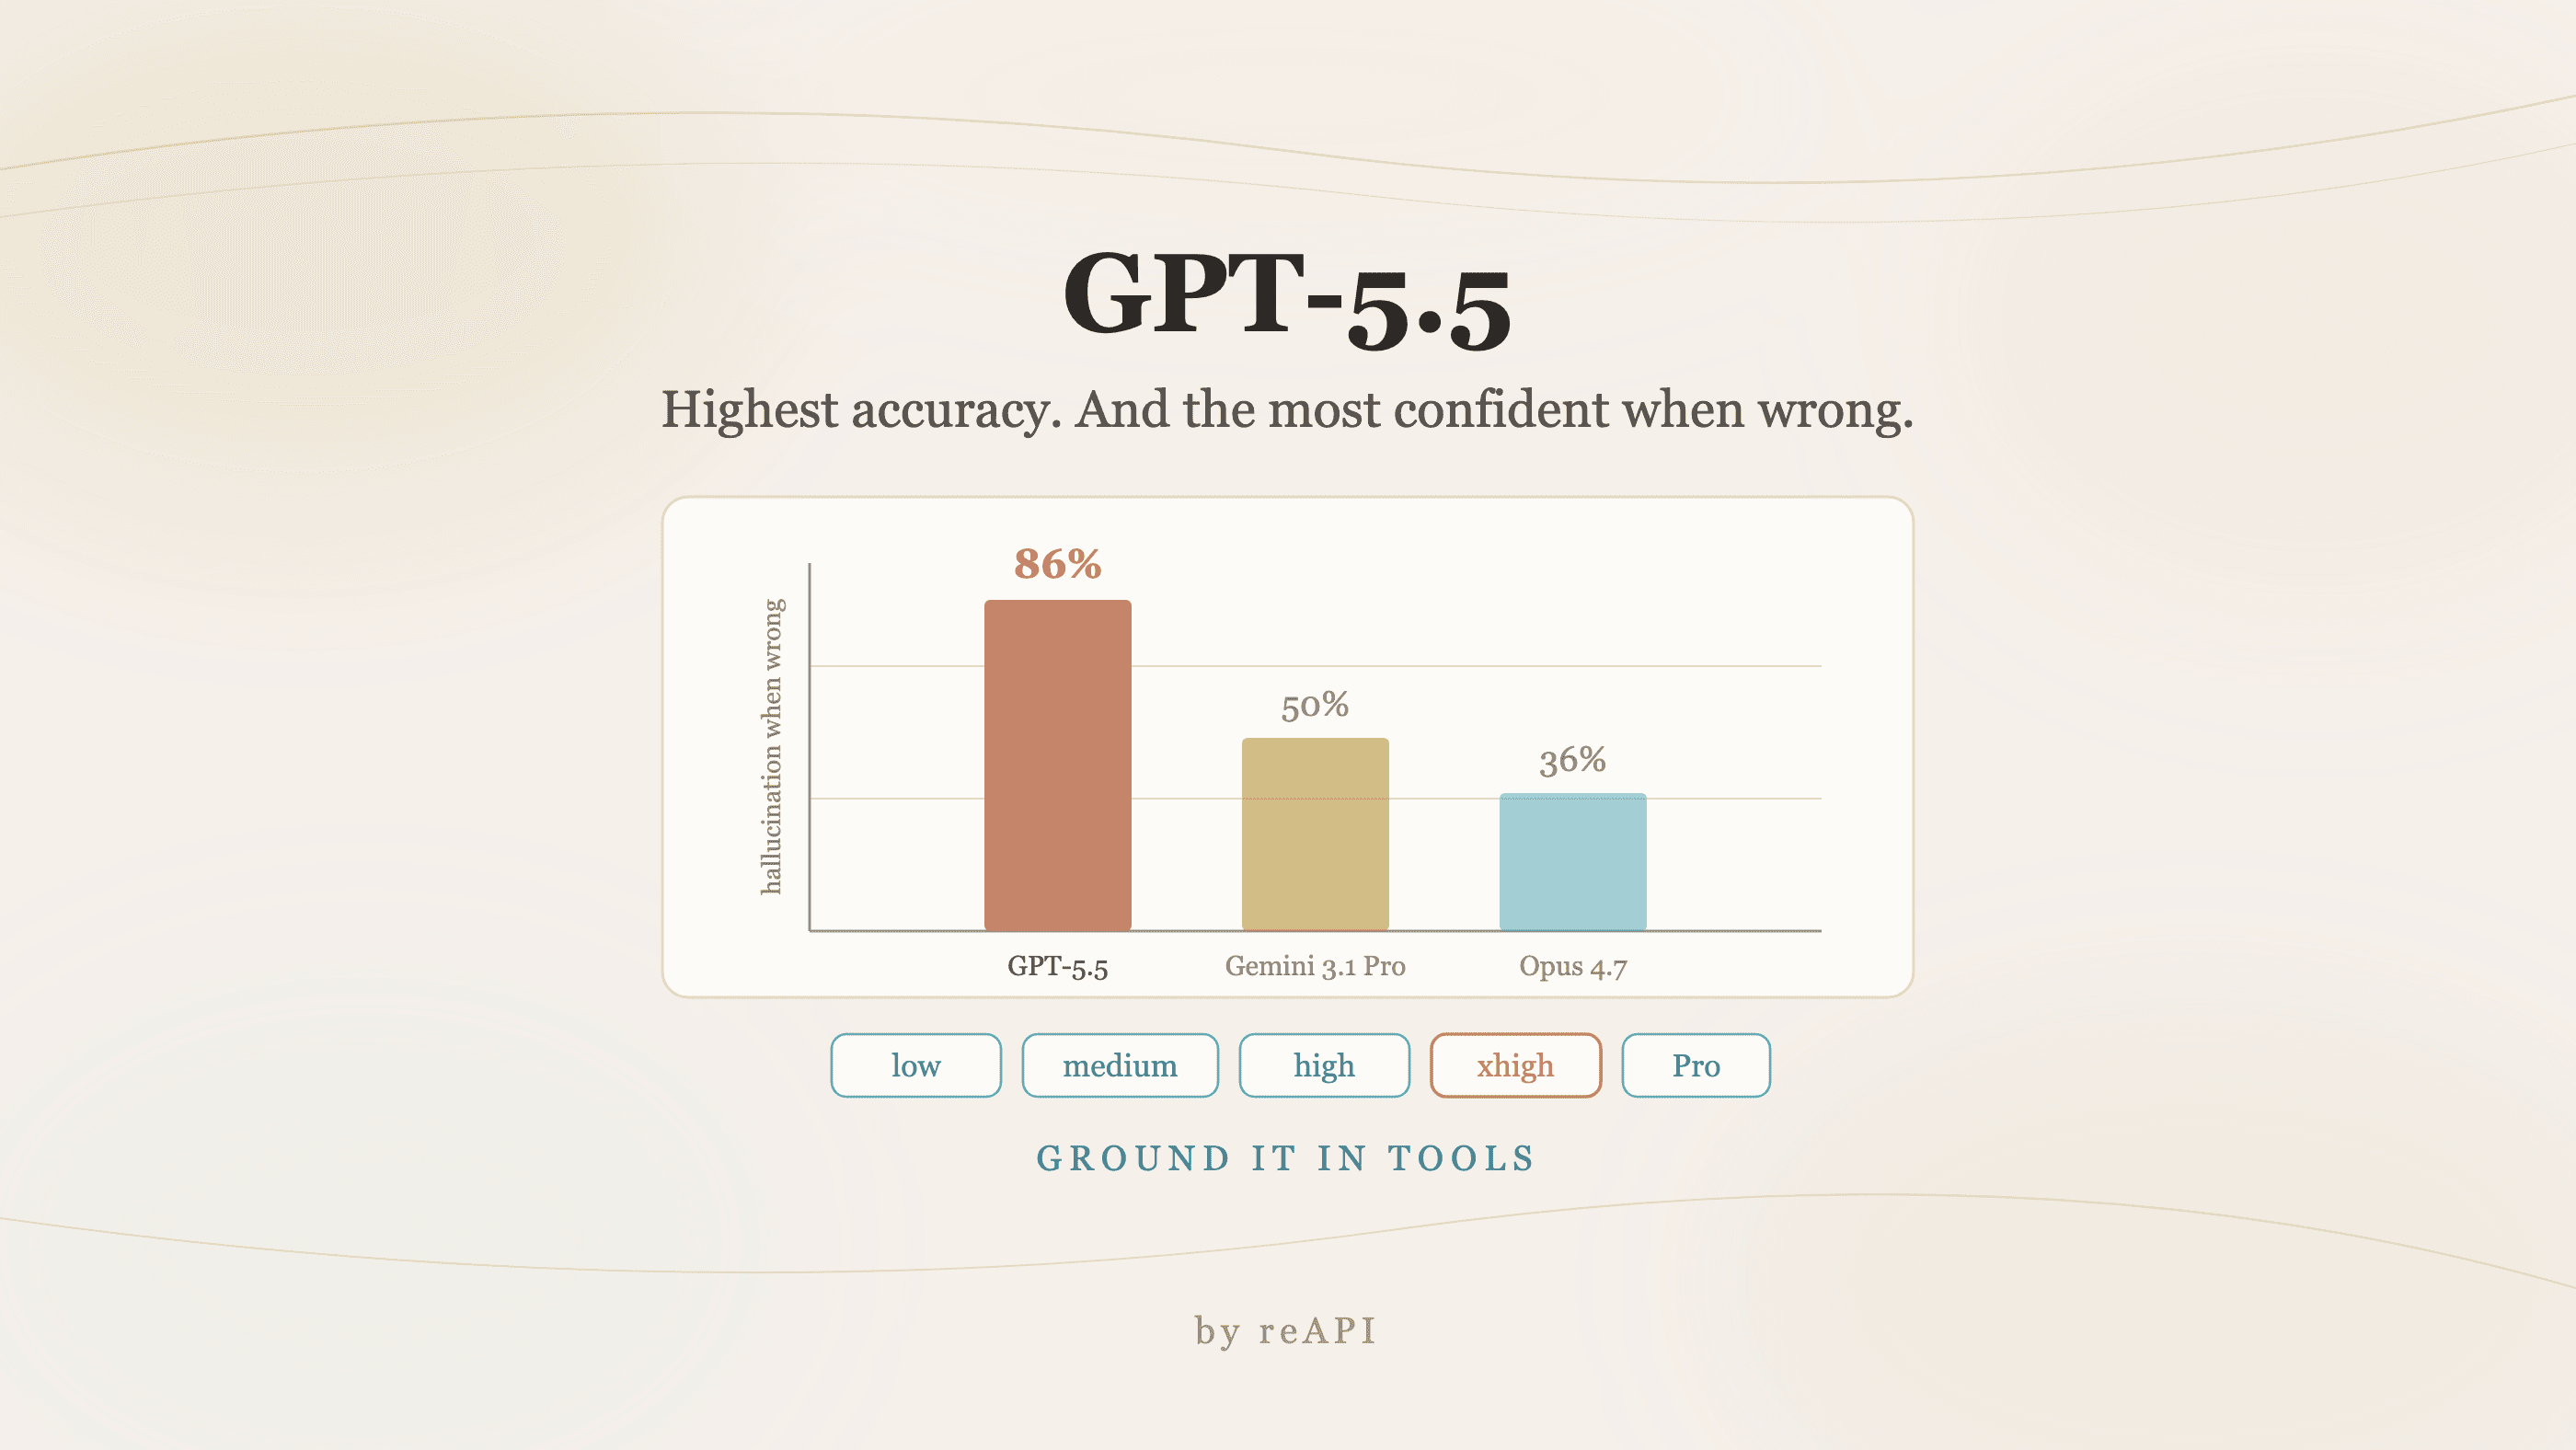
How to Use GPT-5.5: Agentic Strengths and Its One Flaw
How to use GPT-5.5: the Terminal-Bench lead, why the price rise is smaller than it looks, the 86% hallucination rate nobody quotes, and the loop it needs.