GPT Image 2.5 is live — OpenAI's newest image model, targeted edits that leave the rest of the frame alone

Gemini Omni API — Google's Any-Input Video Model

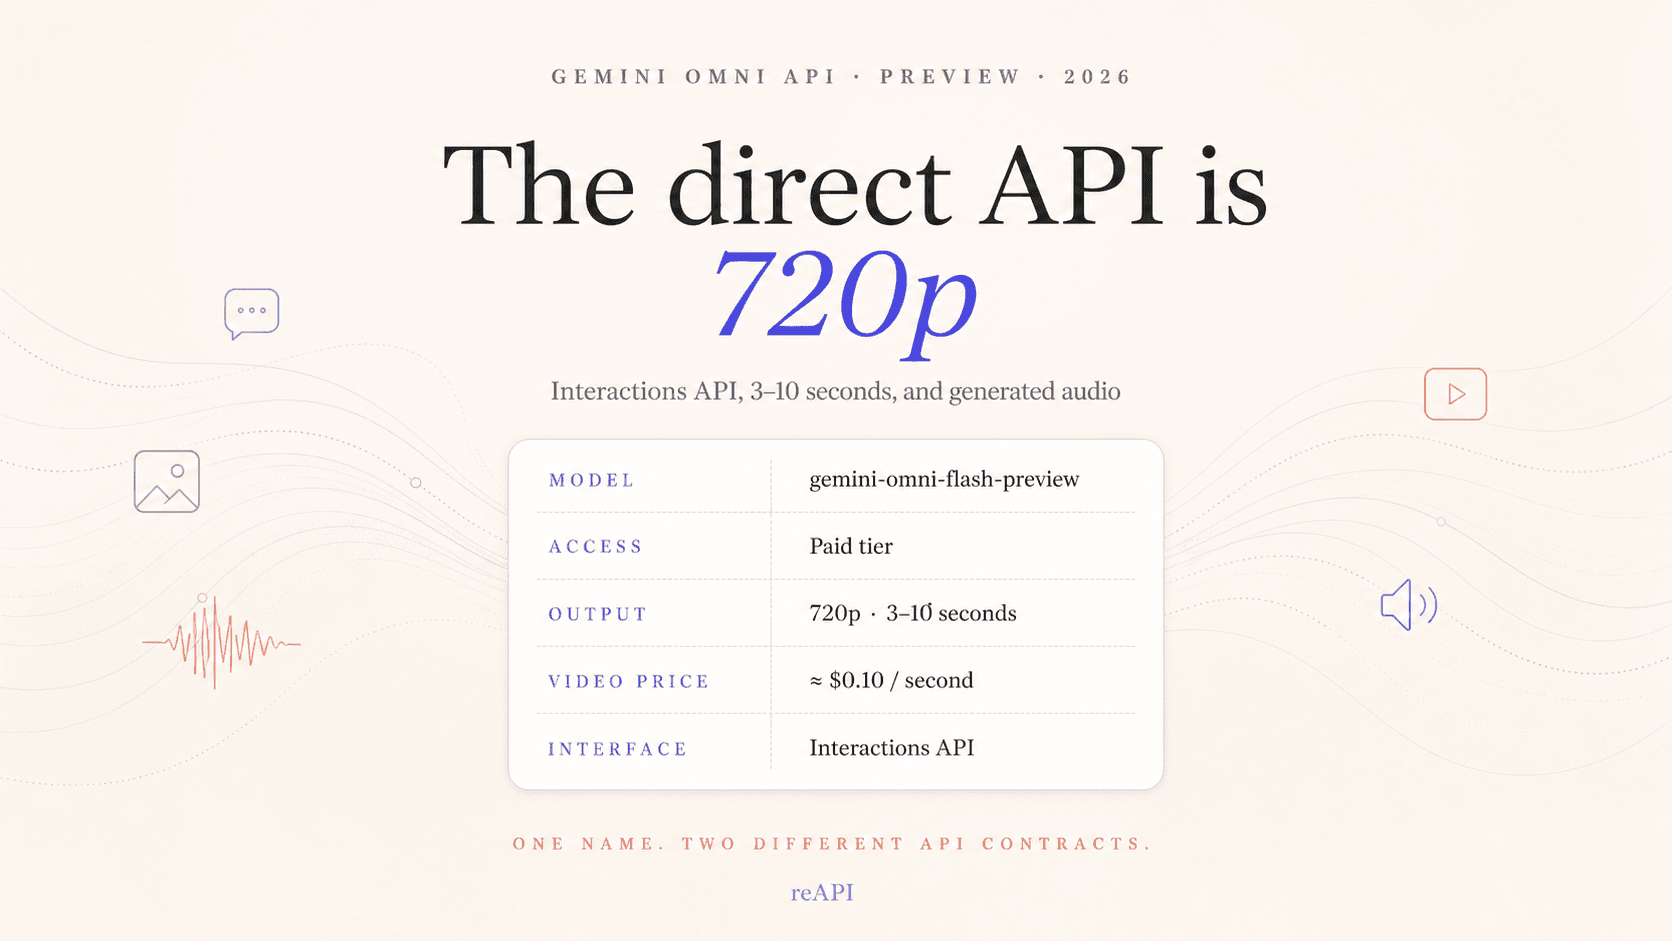
The Gemini Omni API turns a prompt, a single image, or three reference images into a 4 to 10 second clip at 720p, 1080p, or 4K. One endpoint covers text-to-video, image-to-video, and three-image fusion — Google's newest video model, billed per generation.

Highlights
4–10 s · 720p / 1080p / 4K · fusion & reference modes
Best for
Story scenes, character-driven clips
Input
Text, up to 3 images, or a video reference
Output
Video (mp4)
Input

≤ 2000 chars · required

Default 720p

16:9 or 9:16 · default 16:9

Default 6 · ignored in reference-to-video mode

Estimated cost~$0.66660 credits
Result

Try one of these prompts

Pricing

Credit-based — 1 credit = $0.001 USD. Pay only for completed generations.

First test cost
$0.495495 credits

One sample at the cheapest tier (1 generation).

Testing budget guide
Add credits
$10
≈ 20 tests
$50
≈ 101 tests
$100
≈ 202 tests
Category
720p
1080p
4K
4 seconds
$0.495
Price · 1 generation
$0.495
Price · 1 generation
$1.155
Price · 1 generation
6 seconds
$0.660
Price · 1 generation
$0.660
Price · 1 generation
$1.320
Price · 1 generation
8 seconds
$0.825
Price · 1 generation
$0.825
Price · 1 generation
$1.485
Price · 1 generation
10 seconds
$0.990
Price · 1 generation
$0.990
Price · 1 generation
$1.650
Price · 1 generation
Reference 720p
$1.320
Price · 1 generation
Reference 1080p
$1.320
Price · 1 generation
Reference 4K
$1.980
Price · 1 generation

What is the Gemini Omni API?

Gemini Omni is Google's any-input video model, exposed on reAPI as one async endpoint with four modes: text-to-video, image-to-video, three-image fusion, and reference-to-video from a source clip of up to 30 seconds. Prompts run up to 2,000 characters, output lands at 720p, 1080p or 4K in 16:9 or 9:16, and durations are 4, 6, 8 or 10 seconds — reference mode takes its length from the source clip instead. Every job is billed flat per generation, not per second.

What you can build with this model

Real-world workflows and production use cases you can build and ship with this model.

Animate a single still with the Gemini Omni API

Pass one reference image and a motion prompt. The Gemini Omni API returns a 4 to 10 second clip from the same endpoint as your text-to-video calls — no model swap, no extra integration. Send a 1080p or 4K request when you want the result production-ready.

Generate a clip
Fuse three references in one Gemini Omni API call

Send three reference images alongside a prompt and the Gemini Omni API combines scene, character, and product into a single motion shot. Skip the storyboard, the masking, and the multi-pass compositing — three-image fusion is the most differentiated mode on the Gemini Omni API and ships from the same /api/v1/videos/generations endpoint as text-to-video.

Text-to-video at 4K via the Gemini Omni API

Describe the scene, pick 4K, and the Gemini Omni API returns a clip at the highest fidelity tier — useful for hero shots, social ads, and landing-page video. Audio is omitted in the reapi surface, so the result drops cleanly into any downstream editor.

Why reAPI for Gemini Omni

One endpoint, three input modes

The Gemini Omni API picks its mode from the count of image_urls you send. Zero gives you text-to-video, one gives image-to-video, three gives three-image fusion — all on the same /api/v1/videos/generations call, with the same authentication and the same task polling pattern. Two images is not supported; the Gemini Omni API will reject that combination at the gateway with a clear 400.

Per-generation pricing, no surprises

The Gemini Omni API charges per generation, not per second. 720p and 1080p share the same rate; only 4K is uplifted. See current per-tier rates in the pricing table on this page. Failed Gemini Omni API jobs refund automatically — your worker never pays for a result you didn't get.

Access without a Google Cloud account

Skip the Google Cloud onboarding, billing setup, and service-account dance. Sign up for reapi, grab a key, and you can call the Gemini Omni API in under a minute. Same model, same outputs — fewer hoops to ship.

Ship the Gemini Omni API in three steps

  1. step 01

    Create an API key

    Sign up and grab a key from the dashboard. Free credits cover your first Gemini Omni API calls — no card required.

    Open
  2. step 02

    Submit a video task

    POST to /api/v1/videos/generations with model = gemini-omni. The Gemini Omni API returns a task ID immediately so your worker can move on.

    Open
  3. step 03

    Poll the result

    GET /api/v1/tasks/:id until status is completed. Download the Gemini Omni API output and ship it.

    Open
docs/api/gemini-omni

API reference

Drop-in code and the full parameter table.

curl -X POST https://reapi.ai/api/v1/videos/generations \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-omni",
    "prompt": "A kitten playing piano, slow camera push-in",
    "duration": 6,
    "resolution": "1080p",
    "aspect_ratio": "16:9"
  }'

Parameter validation failed

Rejected synchronously with the failing field named. Check enum values, ranges, and URL fields — nothing is charged.

Authentication or balance issue

401 means a missing or invalid Bearer key; 402 means the reserve exceeds your balance. Manage keys and credits in the console.

Content or material rejected

Reference material and outputs pass automated moderation. Rejected tasks fail with a clear error and a full refund.

Task failed or timed out

A task that reaches a failed state is never charged — the reserve refunds automatically. Keep the task id and retry when ready.

Frequently asked questions

Common questions about this model.

Gemini Omni is Google DeepMind's any-to-any multimodal model family announced at Google I/O 26. The Gemini Omni API in reapi is the video-generation surface of that family — submit a prompt and optionally up to three reference images, and the Gemini Omni API returns a 4 to 10 second clip at 720p, 1080p, or 4K. One endpoint covers text-to-video, image-to-video, and three-image fusion.

start building

Ready to ship?

Try it in the playground or grab an API key to integrate now.