The debugging and review work that has to be right
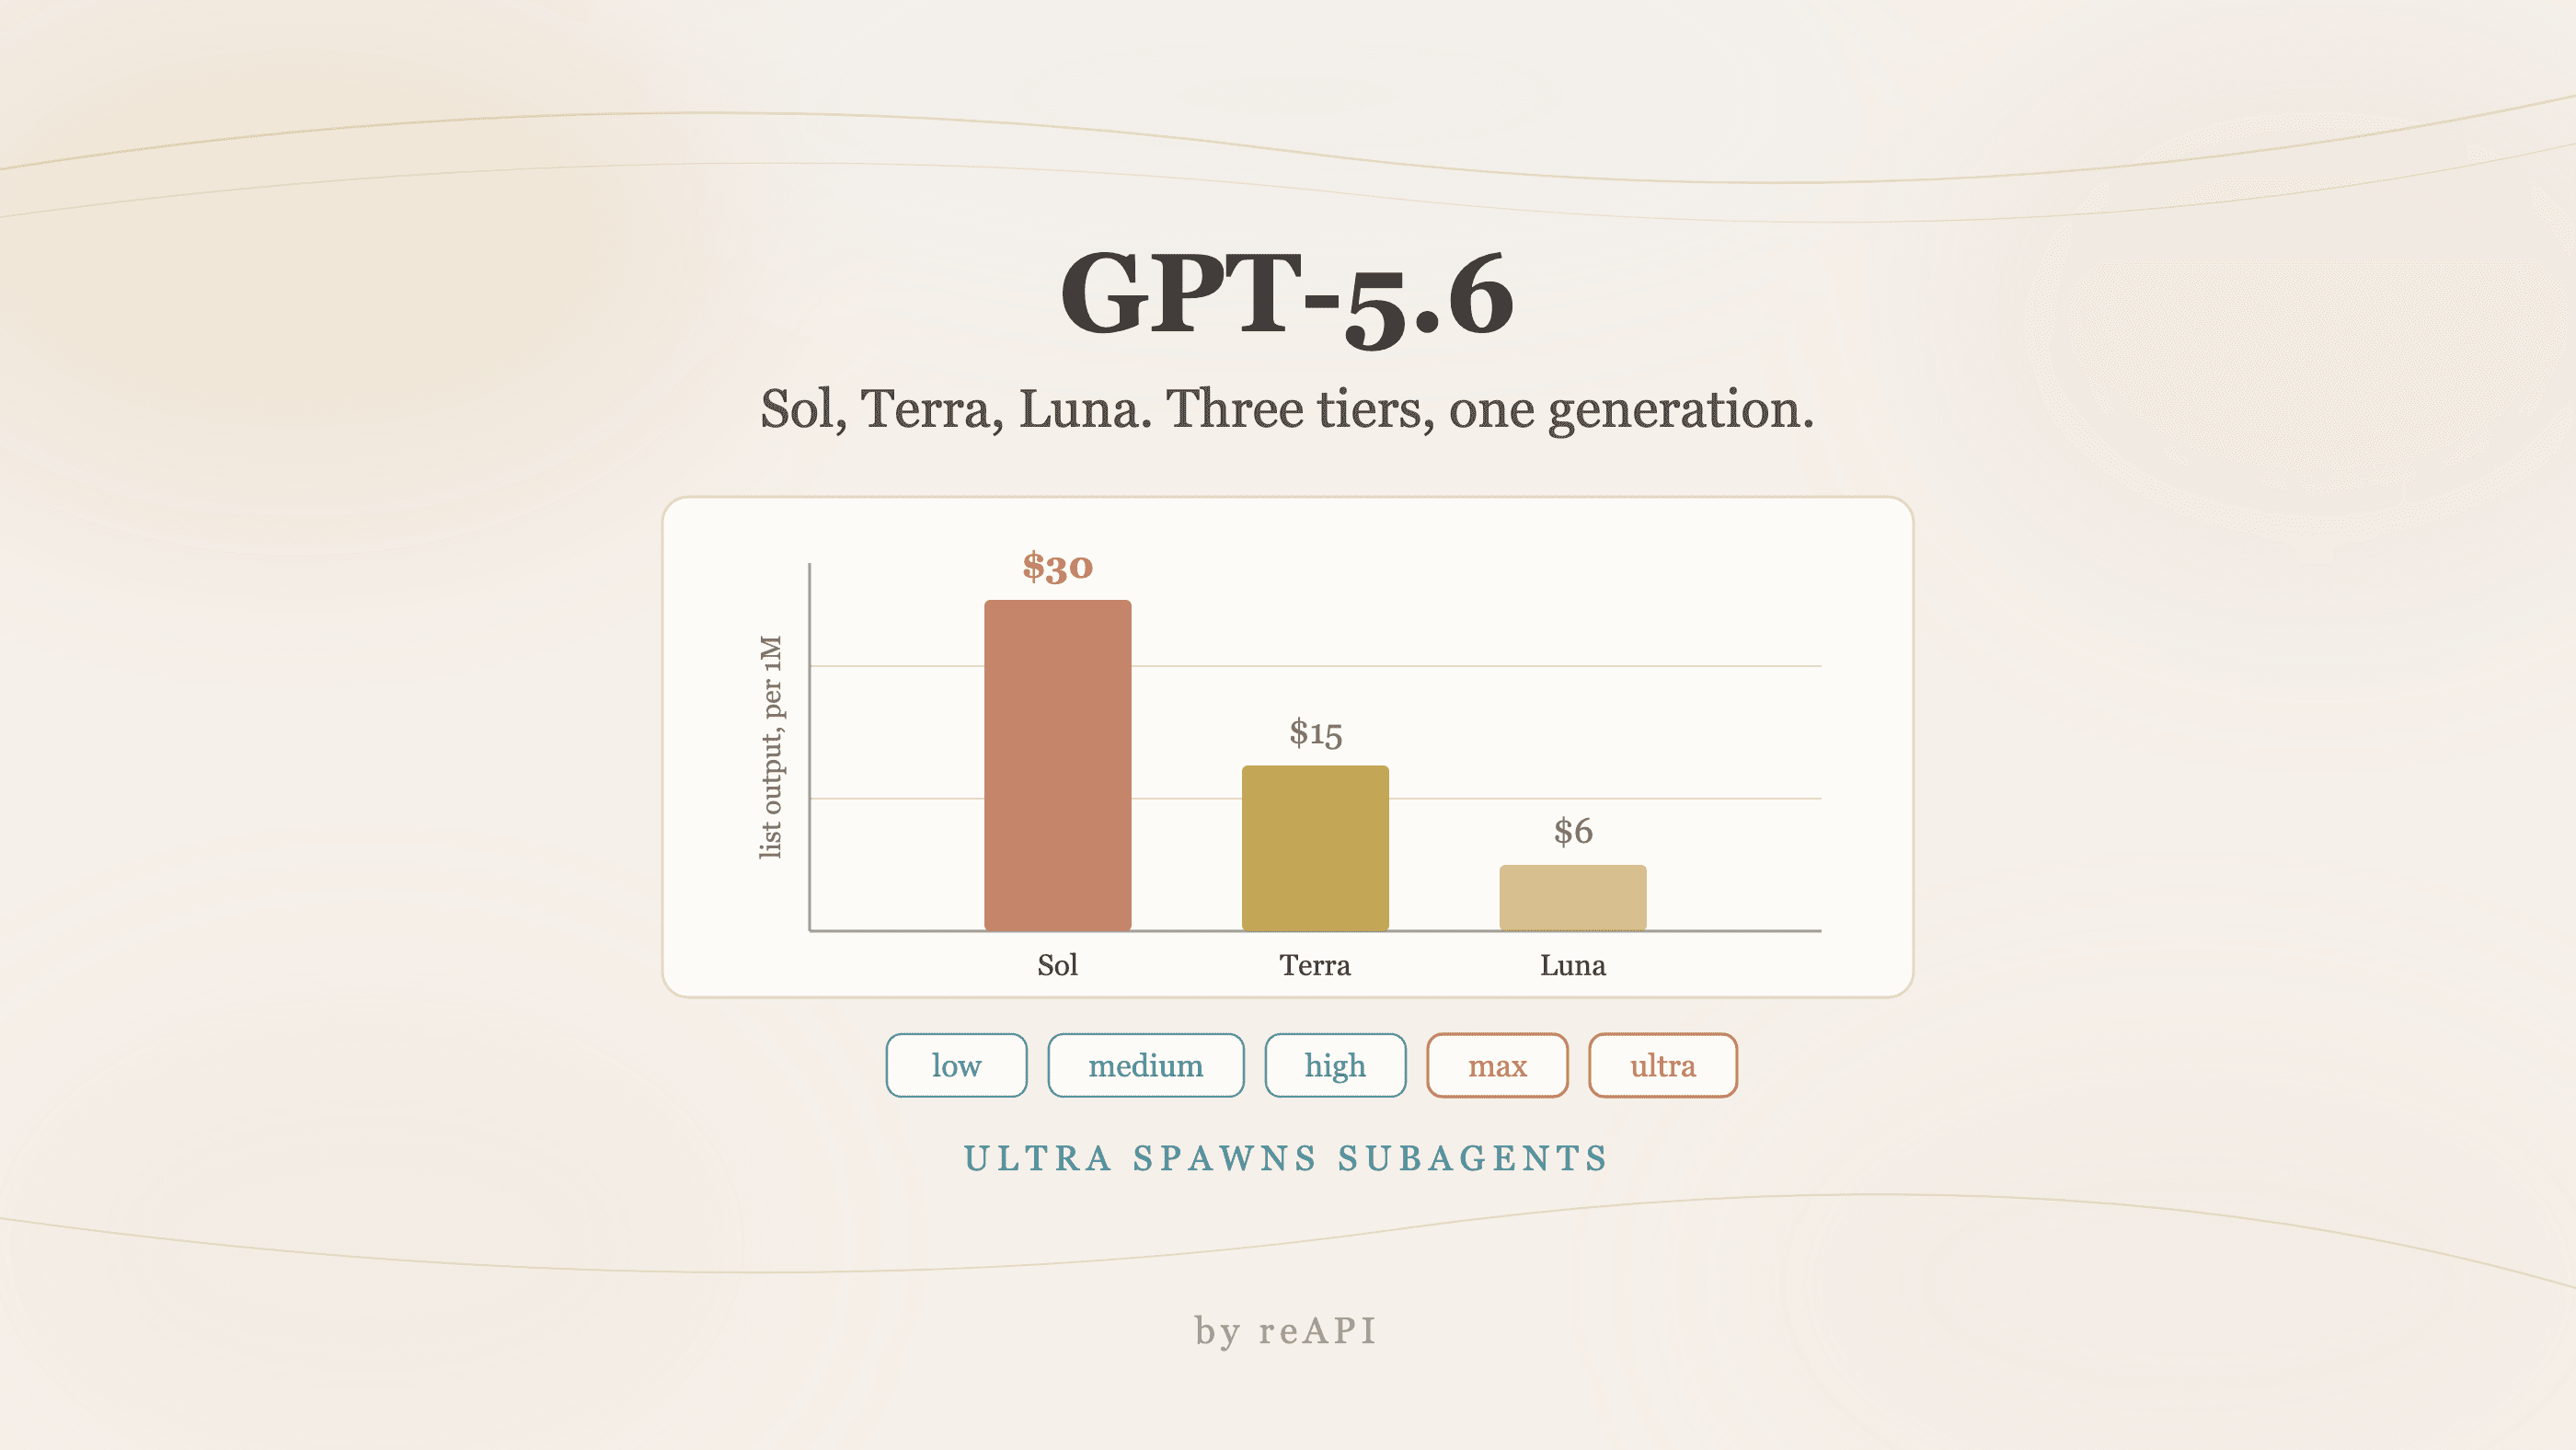
OpenAI's guidance for the top of the effort ladder names security and code review, complex debugging and deep planning — tasks where quality matters more than latency. GPT-5.6 Sol is the tier those settings were built for, and the shape of the work follows from the limits: a 1,050,000-token window means the service, its tests and its recent history all go into one request, so the model is reasoning about the actual system rather than a summary of it. Ask GPT-5.6 Sol to prove a cause before proposing a fix and the deep pass earns its cost; ask it to guess quickly and you are paying frontier rates for a cheap tier's job.
Read the API docs