AI Video Generator With Real People: What Actually Works
Use an AI video generator with real people: supported reference inputs, native dialogue options, documented limits, moderation, and cost.
Can you use an AI video generator with real people? Yes, when the subject has consented and the selected route documents real-person references. The practical questions are whether the input is accepted, whether the model generates speech, how review works, and what the job costs.
The useful split is not by tool. It is by whose face it is. A photograph of a consenting subject, a synthetic character and a named celebrity are legally and technically distinct inputs. This guide explains the documented path for each case, what talking requires, and what to check when a reference is refused.
TL;DR
- Reference photos and clips of real people are supported. Seedance 2.5's parameter reference states plainly that "reference images / videos may contain real people."[1]
- Rejected reference material refunds in full. Material passes automated review before generation, and anything refused fails with an error and a full refund of the reserve.[2]
- Talking is a separate capability. Seedance 2.5 generates "synced speech, sound effects and background music" with
generate_audio, on by default.[1] Kling 3.0 documents lip sync explicitly.[3] - Named celebrities are refused on every route. That is the model's own line, not a platform policy setting, and no parameter reaches it.
- Consent is still yours to obtain. An API that accepts an upload has not acquired permission on your behalf.
Four different asks wearing one search term
Your own footage, or a consenting subject. This is the largest legitimate case: founders in their own product demos, UGC creators, actors who signed a release, a client whose brand video you are making. It is supported, and the rest of this article is mostly about it.
A synthetic person whose reference is refused. The error alone does not prove how a review system classified the image or which internal check made the decision. Check the documented input requirements and review result before deciding what caused it.
A named public figure. Refused. Not by reAPI as a matter of policy, but by the model, on every host that resells it. Any platform advertising otherwise is either wrong or selling you a likeness-rights problem.
People talking. A capability question rather than a permission question, and it is answered by which model you pick rather than by which platform.
Keep these cases separate when troubleshooting. A supported real-person reference, a refused synthetic reference and a request for a named person do not have the same next step.
Using a consented person as a reference
The supported path is reference material, not prompting a description. Seedance 2.5 takes up to 30 reference images, 10 reference clips and 10 audio tracks in one generation.[1]
curl https://reapi.ai/api/v1/videos/generations \
  -H "Authorization: Bearer rk_live_your_key" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "doubao-seedance-2.5-face",
    "prompt": "@Image1 walks through a sunlit workshop, handheld follow",
    "resolution": "720p",
    "duration": 8,
    "image_urls": ["https://your-cdn.example.com/subject-01.jpg"]
  }'
The constraints worth knowing before you assemble a reference set:[1]
| Field | Limit | Formats |
|---|---|---|
image_urls | up to 30, each under 30 MB | jpeg, png, webp, bmp, tiff, gif, heic, heif |
video_urls | up to 10, each 2–30 s, under 200 MB, combined 30 s | mp4, mov, 480p to 4K |
audio_urls | up to 10, each 2–30 s, under 15 MB | wav, mp3 |
Two rules catch people out. Every reference must be a public HTTP(S) URL; base64 and data: payloads are rejected across the whole platform, not just this model.[1] And image_urls cannot be combined with image_with_roles, so character references and first/last-frame chaining are separate modes.[1]
Reference material goes through automated review before generation runs. If it is refused, the task fails with an error and the reserve is refunded in full,[2] so a rejected attempt costs time rather than the reserved amount.
Making them talk
This is where model choice matters more than platform choice, and the two documented options behave differently.
Seedance 2.5 generates audio natively. generate_audio defaults to true and produces "synced speech, sound effects and background music (mono)."[1] The speech is generated with the video rather than dubbed onto it, so mouth movement and audio come from the same pass. You direct it through the prompt.
Kling 3.0 documents the capability more specifically, describing synchronized native audio as "dialogue, lip sync, ambient sound."[3] If lip sync accuracy on dialogue is the thing you are being judged on, that is the explicit claim to test against.
What neither offers is a dubbing mode where you supply a finished voice track and get precise mouth-shape matching to it. Seedance 2.5's audio_urls are documented as reference audio tracks,[1] which is a different job from lip-sync driving. If your pipeline already has recorded VO, test that assumption on a short clip before you build around it.
One practical note for talking-head work: audio does not survive segmentation. Each generation synthesises its own track, so a sequence assembled from several clips gives you several independent audio beds. For dialogue longer than one generation, record or synthesise the voice separately and treat the video as picture only.
The line that does not move
Named living people are refused. Every honest route enforces this, and it sits with the model rather than with any platform's settings. If a host claims otherwise, the correct response is suspicion, not a signup.
Third-party characters are refused too. The same check catches recognisable copyrighted characters, which is a recurring frustration for anime and fan work and has no workaround worth publishing.
Consent is not transferred by an upload form. The API accepting your reference photo is not permission from the person in it. Releases, likeness rights and, in several jurisdictions, biometric-data rules are your responsibility and do not become the platform's because a request returned 200.
That last one is not legal boilerplate. It is the reason the supported path exists at all: the check is designed to stop the non-consensual case, and it works better when the legitimate case has somewhere to go.
When a synthetic reference is refused
A refusal message does not establish whether the reference was rejected because of its content, its format, or another review rule. Do not infer the internal mechanism from the wording alone. First confirm that the URL, file type, size, duration and field combination match the published parameter reference.[1]
If the input is valid but automated review still rejects it, treat that result as a moderation outcome rather than proof about the image's origin. Try another compliant reference or a model whose documented input policy fits the job. The face-detected troubleshooting guide separates input validation from review without guessing which internal system produced the message.
What it costs
Reference-driven work is priced the same as any other generation on Seedance 2.5, with one wrinkle. Reference images and audio do not change the rate; a reference video moves you to a lower per-second rate. reAPI then bills max(output + ceil(total source-video duration), ceil(5 / 3 × output)) seconds.[2]
| Job, 720p | Cost |
|---|---|
| 8 s from reference images | $2.135 |
| 30 s from reference images | $8.005 |
| 10 s reference clip to 5 s output | $2.402 |
Rates from the published per-second band.[2] A failed moderation check refunds in full, so exploratory reference sets cost time rather than credits.
FAQ
Can I use an AI video generator with real people at all?
Yes, with reference material of a consenting subject. Seedance 2.5's parameter reference states that reference images and videos may contain real people.[1]
Can I generate a famous person?
No. Named public figures are refused at the model level on every route, and no parameter changes that.
Which model handles people talking?
Seedance 2.5 generates synced speech alongside the video with generate_audio.[1] Kling 3.0 documents dialogue and lip sync explicitly.[3]
Can I supply my own voice recording and get lip sync to it?
Not as a documented mode. Seedance 2.5's audio_urls are reference tracks rather than a lip-sync driver.[1] Test it on one short clip before designing a pipeline around it.
Why was my AI-generated character rejected as a real person?
The message does not reveal the internal reason. Verify the reference URL, format, size and field combination first; if those are valid, handle the result as a review rejection. The face-detected explainer gives a documented checklist.
Do I get charged when a reference is rejected?
Not on reAPI. A task that fails review refunds the reserve in full.[2]
Can I upload the reference file directly?
No. Every reference must be a public HTTP(S) URL. Base64 and data: payloads are rejected platform-wide.[1]
How many reference images can one generation take?
Up to 30, plus 10 clips and 10 audio tracks.[1]
Working with faces instead of around them
Decide which of the four asks you actually have before you pick a tool. A consenting subject and a valid reference set form a supported workflow with published parameters and a refund when review says no. A refused synthetic reference needs an input-and-review check, not a guess about the hidden classifier. Dialogue remains a model-selection question with two documented answers.
Only the fourth ask, a named person who did not agree, has no route, and that is worth defending rather than routing around. An AI video generator with real people is a normal tool when the people said yes, and the reason the supported path stays open is that the unsupported one stays closed.
Full parameter reference at reapi.ai/docs/seedance-2-5; current rates on the Seedance 2.5 model page.
References
- reAPI. doubao-seedance-2.5-face — request body, reference limits,
generate_audioand platform media rules. Retrieved August 2026 from reapi.ai/docs/seedance-2-5 - reAPI. Seedance 2.5 — model page, real-person reference support, published rates and refund behaviour. Retrieved 9 August 2026 from reapi.ai/models/seedance-2-5
- reAPI. Kling 3.0 — native audio with dialogue and lip sync. Retrieved August 2026 from reapi.ai/docs/kling-3-0
Further reading
- reAPI. Seedance Face Detected: Real Person Errors, Explained. reapi.ai/blog/seedance-face-detected-real-person-error
- reAPI. AI Video Generator Long Videos: Chaining Past the Cap. reapi.ai/blog/ai-video-generator-long-videos
Author

Categories
More Posts
Midjourney V8.2 Features and the Nine Flags V8 Retired
Midjourney V8.2 dropped nine features V6 and V7 had, including Quality and Turbo. What still works, what silently falls back to V7, and what HD really costs.
Best Seedance 2.5 Alternatives: H3, Veo, Sora and More
Compare the best Seedance 2.5 alternatives for video generation, including MiniMax H3, Seedance 2.0, Veo 3.1, Sora 2, Runway, and Kling 3.
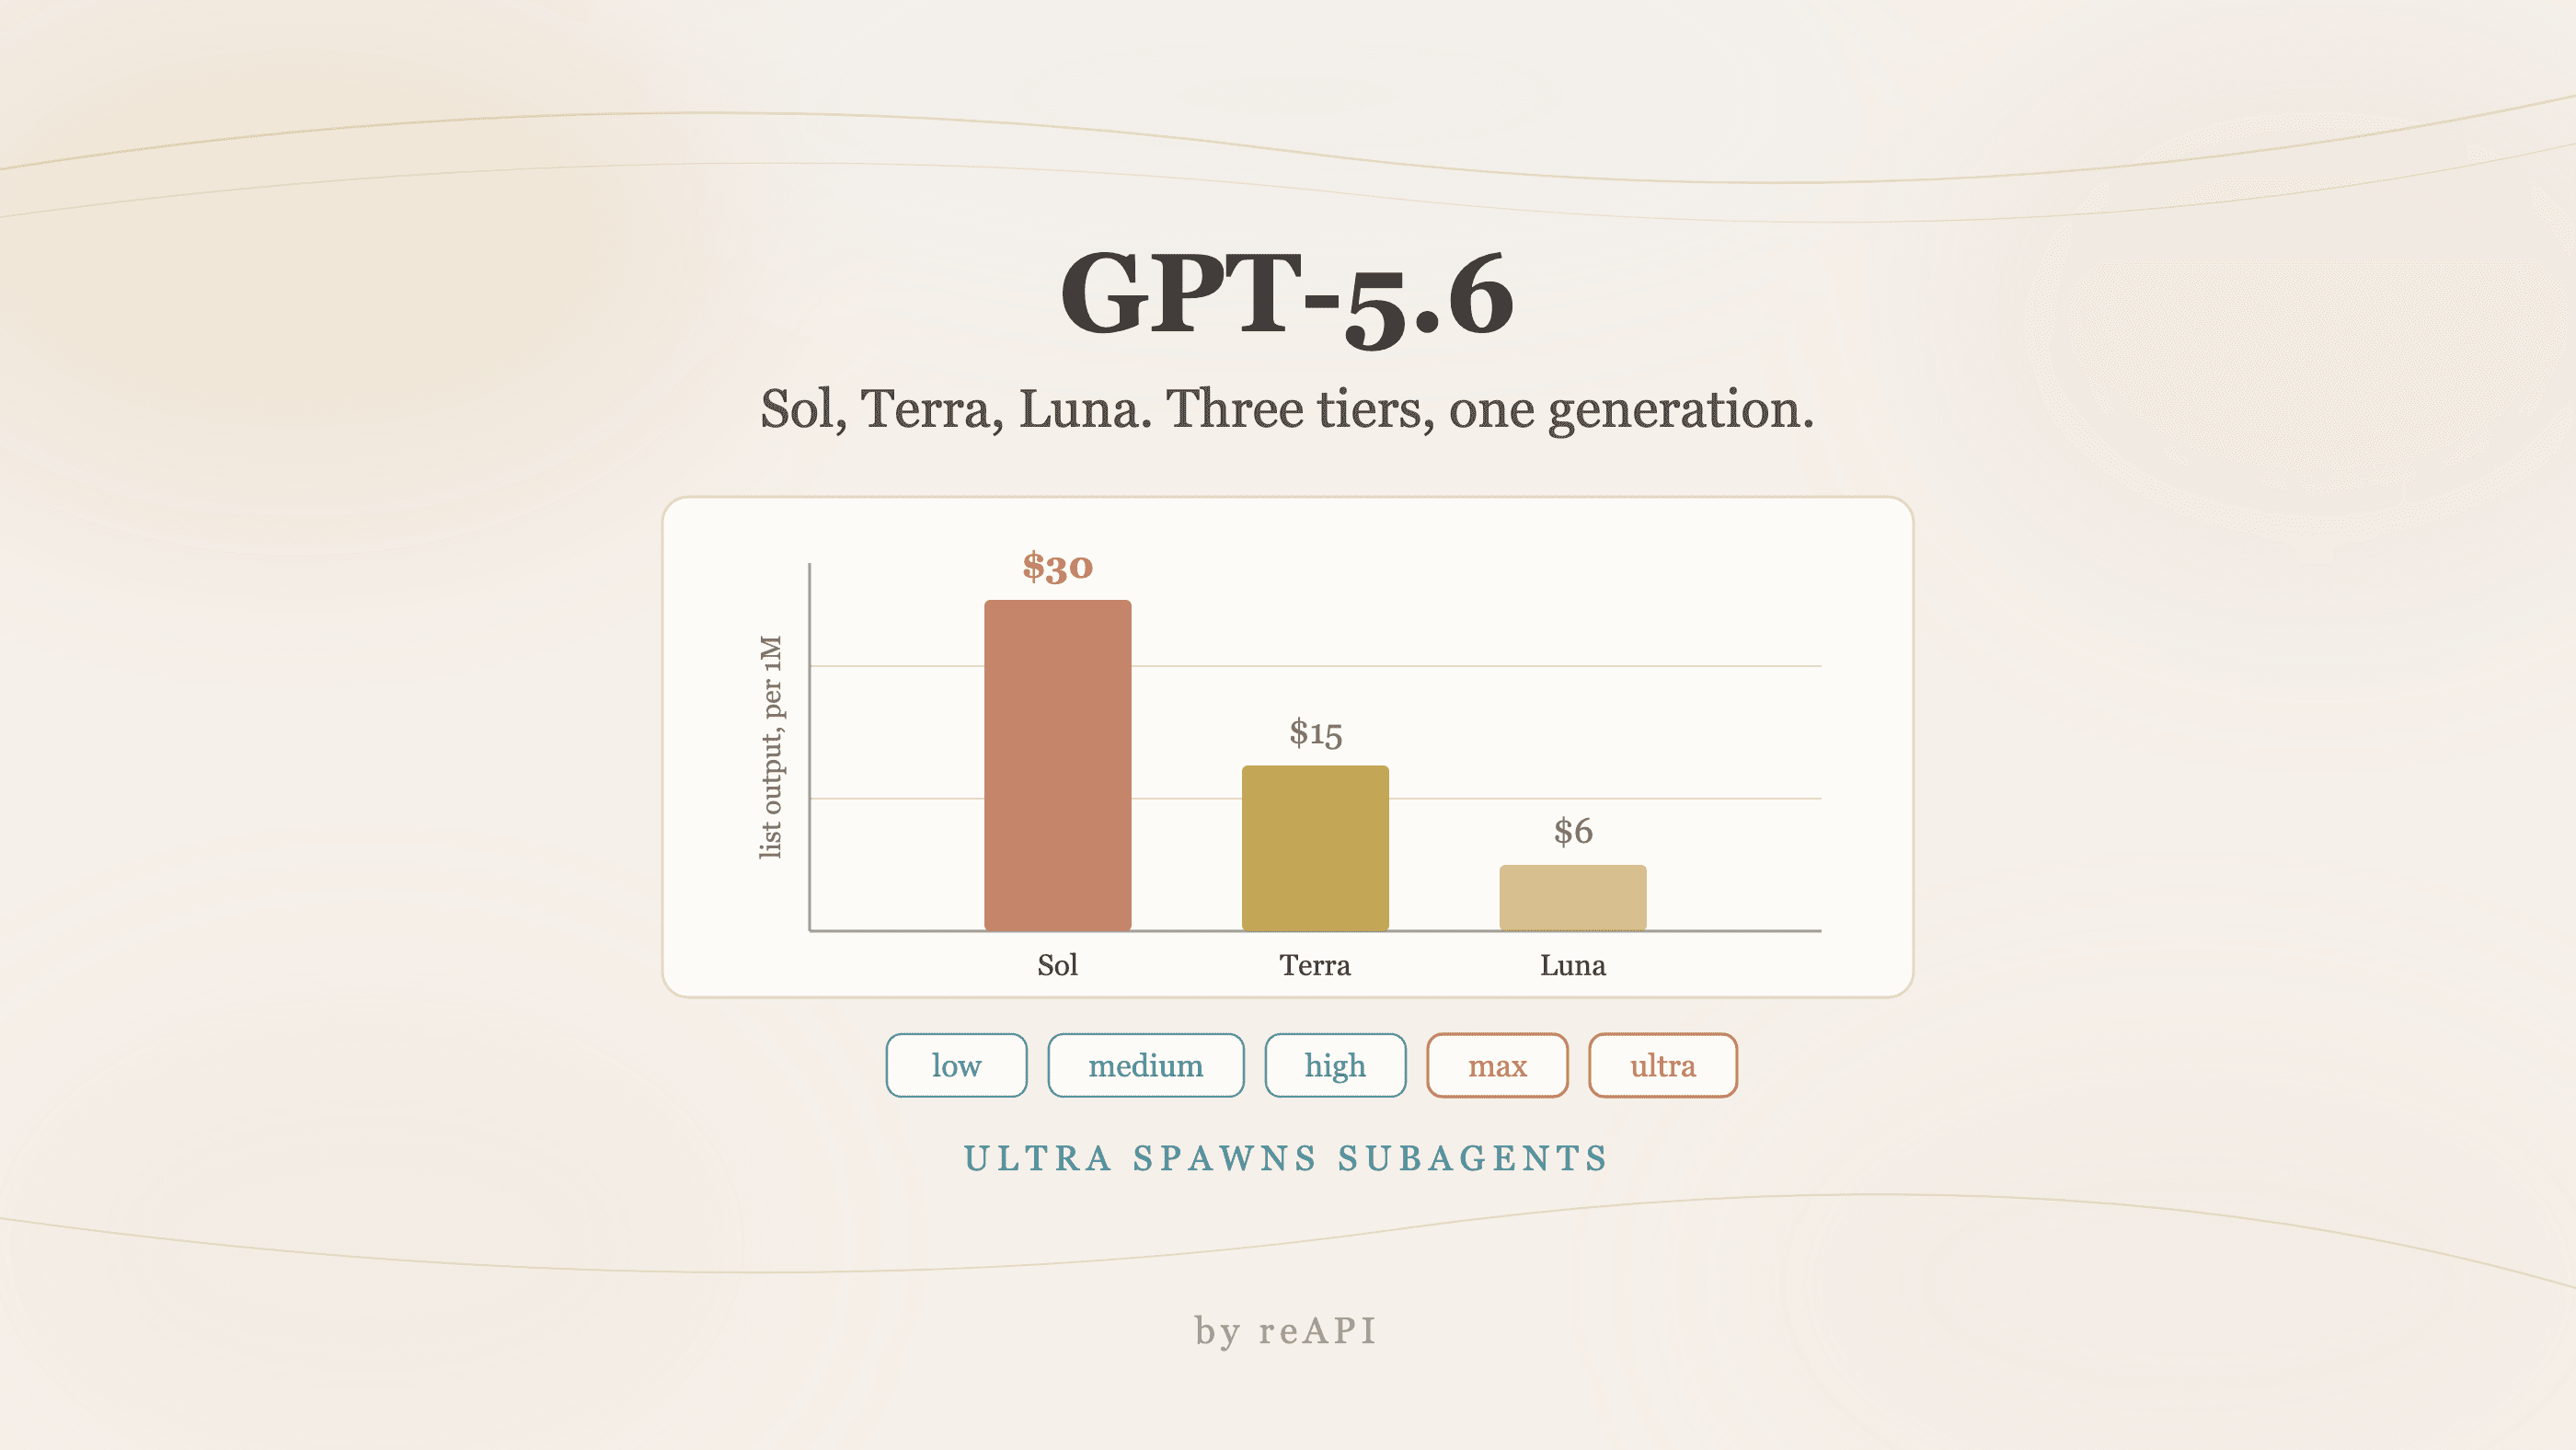
How to Use GPT-5.6: Sol, Terra, and Luna Tiers Compared
How to use GPT-5.6: what Sol, Terra, and Luna cost, the Terminal-Bench table and its four asterisks, the new max and ultra modes, and which tier to pick.