GPT-6 Luna API Set Temperature: Why It Returns 400 and What to Send
Trying to set temperature on the GPT-6 Luna API? Why GPT-6 Luna and Sol return 400 for temperature and top_p, the exact model ID, and a fixed request.
If you try to set temperature on the GPT-6 Luna API, the usual result is an HTTP 400, not a cooler answer. OpenAI's GPT-6 migration guide tells developers to remove temperature, top_p and top_logprobs whenever reasoning effort is anything other than none, and to drop logprobs on Chat Completions as well[1]. GPT-6 Luna defaults to medium effort[2], so a request that adds temperature: 0.2 and leaves effort alone falls on the wrong side of that rule.
This article covers what the rule says, the exact error strings developers have posted from Amazon Bedrock, Azure and OpenAI clients, the correct model ID, and a before-and-after request for reAPI's Chat Completions endpoint. The same rules apply to GPT-6 Sol.
TL;DR
- Remove
temperatureandtop_p. OpenAI's guide says to remove them, plustop_logprobs, when reasoning effort is notnone[1]. Luna's default effort ismedium[2]. - On reAPI the rule is simpler:
temperature,top_p,frequency_penaltyandpresence_penaltyreturn400on bothgpt-6-lunaandgpt-6-sol. Leave them out of every request[3][4]. - Even
temperature: 1can fail. A Langflow bug report found Amazon Bedrock's Converse API rejects the field at any value, including 1[5]. - The control you do get is
reasoning_effort:none,low,medium,high,xhighormax[2]. There is noautovalue. - The model ID is
gpt-6-luna(andgpt-6-sol), exactly as written[2][3]. - The top Microsoft Q&A result is a different bug. It is about
reasoning.effortbeing rejected in Azure AI Foundry, not about temperature[6].
Why GPT-6 Luna rejects temperature
GPT-6 Luna is a reasoning model. OpenAI's model page lists "Reasoning token support" and six effort levels, with medium as the default[2]. The "Update API and model parameters" checklist in OpenAI's GPT-6 guide puts the sampling knobs under a heading of their own[1]:
Unsupported parameters: When reasoning effort is not none, remove temperature, top_p, and top_logprobs. For Chat Completions, also remove logprobs.
Read the condition carefully. The guide ties the removal to reasoning effort, not to the model name. The same guide notes that GPT-6 Sol and GPT-6 Luna support none, while GPT-6 Astra and GPT-6.1 Sol do not[1]. In practice most requests run at the default medium, so most requests that carry temperature fail.
reAPI documents a stricter result. Its parameter table for gpt-6-luna, measured on the endpoint on 2026-09-24, lists temperature, top_p, frequency_penalty and presence_penalty as "Not supported by this model — sending any of them returns 400. Leave them out of the request."[3] The gpt-6-sol page carries the same row[4]. The docs describe no exception for none effort, so don't build on one: strip the fields.
The 400 messages developers are actually hitting
Search results for this problem mix several distinct errors. These are the strings people have posted publicly, where each one came from, and what fixes it.
| Error text, as reported | Where | Fix |
|---|---|---|
| "Only the default (1) value is supported." | Bedrock's OpenAI-compatible endpoint, Langflow sending temperature 0.1[5] | Remove temperature |
| "This model doesn't support the temperature field. Remove temperature and try again." | Bedrock Converse, from Langflow (default 0.7) and Phoenix (default 1)[5][7] | Remove temperature, then top_p, which Converse rejects the same way[5] |
| "Unsupported parameter: 'reasoning.effort' is not supported with this model." | Azure AI Foundry agents and the Foundry project endpoint[6][8] | Not a temperature issue; see the Azure answer in the FAQ |
| "Function tools with reasoning_effort are not supported for gpt-6-luna in /v1/chat/completions. To use function tools, use /v1/responses or set reasoning_effort to 'none'." | OpenAI Chat Completions, from a Ruby client sending tools[9] | Use the Responses API or effort none, per OpenAI's model page[2] |
| "Invalid parameter: 'text.format' of type 'json_schema' is not supported with model version gpt-6-luna-2026-09-22" | A Foundry Agent definition[10] | Reported against Azure; not a temperature issue |
Two of these reports show the field arriving without anyone choosing it. Phoenix's AWS playground starts every run with temperature: 1 from a default config, and its slider cannot be cleared[7]. Langflow's Bedrock component sends Temperature 0.7 and Top P 0.9 by default[5]. So if your own code never mentions temperature and you still get the error, look at the framework's defaults.
GPT-6 Luna API set temperature on reAPI: before and after
reAPI serves GPT-6 Luna through POST https://reapi.ai/api/v1/chat/completions with your reAPI key as a bearer token[3]. This request carries habits from older chat models and will be rejected:
# Rejected: temperature and top_p return 400 on gpt-6-luna
curl https://reapi.ai/api/v1/chat/completions \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-luna",
    "messages": [
      { "role": "user", "content": "Classify this ticket as billing, bug or account access: I was charged twice." }
    ],
    "temperature": 0.2,
    "top_p": 0.9
  }'
The corrected version drops both fields and sets the controls the model does honour. reasoning_effort accepts all six levels on reAPI, and max_completion_tokens is applied up to 128,000[3]:
# Accepted: no sampling fields, explicit effort and output cap
curl https://reapi.ai/api/v1/chat/completions \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-luna",
    "messages": [
      { "role": "user", "content": "Classify this ticket as billing, bug or account access: I was charged twice." }
    ],
    "reasoning_effort": "low",
    "max_completion_tokens": 1000
  }'
Reasoning tokens count toward max_completion_tokens and bill as output, so a cap sized only for the visible answer can truncate a harder prompt[3]. Current per-token rates are on the GPT-6 Luna model page.
The rest of the parameter surface on reAPI, as documented for both GPT-6 models[3][4]:
| Field | Result on gpt-6-luna and gpt-6-sol |
|---|---|
temperature, top_p, frequency_penalty, presence_penalty | 400, leave them out |
seed, stop, logprobs, verbosity | Accepted (200) but no effect |
n | Only 1; a larger value returns 400 |
reasoning_effort | none, low, medium, high, xhigh, max; medium when omitted |
response_format | Applied, including json_schema with strict |
tools, tool_choice | tool_calls returned at medium effort as well as none |
The tools row differs from OpenAI's own Chat Completions rule, which allows function calling only at reasoning_effort: "none"[2]. On reAPI's endpoint, tools returned tool_calls at medium in the 2026-09-24 measurement[3].
What to use instead of temperature
Temperature controlled randomness in sampling. GPT-6 Luna gives you no direct replacement for that, so pick the control that matches what you wanted temperature for.
You wanted consistent, parseable output. Use response_format with a JSON schema and strict: true. reAPI applies it on both GPT-6 models[3], and a strict schema fixes the shape of the answer, which is what many temperature: 0 settings were trying to get.
You wanted faster or cheaper answers. Lower reasoning_effort. OpenAI's reasoning guide describes none for latency-critical work such as classification and fast retrieval, and low for tool use, support workflows and drafting[11]. Fewer reasoning tokens also means fewer output tokens billed[3].
You wanted varied answers. Neither seed nor n helps here on reAPI. seed is accepted with no effect and n is limited to 1[3]. Send separate requests, or ask for several alternatives in one prompt.
You wanted a different style. Say so in the system or developer message. Sampling settings were always a blunt tool for tone, and the instructions are the only lever left.
Stripping the fields in Python
If a shared helper or config injects sampling defaults, remove them before the call rather than editing every caller. This uses the official OpenAI SDK pointed at reAPI, as in reAPI's Python example[3]:
from openai import OpenAI

client = OpenAI(api_key="YOUR_API_KEY", base_url="https://reapi.ai/api/v1")

REJECTED = {"temperature", "top_p", "frequency_penalty", "presence_penalty"}

def gpt6_params(params: dict) -> dict:
    """Drop fields that gpt-6-luna and gpt-6-sol answer with 400."""
    return {k: v for k, v in params.items() if k not in REJECTED}

params = {"temperature": 0.2, "top_p": 0.9, "max_completion_tokens": 1000}

resp = client.chat.completions.create(
    model="gpt-6-luna",
    messages=[{"role": "user", "content": "Summarize this refund policy in two sentences."}],
    reasoning_effort="low",
    **gpt6_params(params),
)
print(resp.choices[0].message.content)
When you can't see where a field comes from, log the keys of the final serialized request body during testing. The Phoenix and Langflow reports above are both cases of a default the caller never wrote[5][7].
FAQ
GPT-6 Luna API set temperature GitHub
The GitHub issues about this are mostly bugs in tools that send temperature by default. Langflow's Bedrock component sends 0.7 and 0.9 for temperature and top_p[5], and Phoenix's AWS playground sends temperature: 1 on every run[7]. Both reports say the request works once the fields are removed. The fix in your own code is the same: don't send temperature or top_p to GPT-6 Luna.
GPT-6 Luna API set temperature Python
You can't set it. Leave temperature and top_p out of client.chat.completions.create(...) and pass reasoning_effort instead. On reAPI both fields return 400[3]. The Python helper above filters them out if they arrive from shared config.
GPT-6 Luna API set temperature example
The corrected cURL request above is the example: model set to gpt-6-luna, the messages array, reasoning_effort: "low" and max_completion_tokens: 1000, with no temperature or top_p. It follows the field rules in reAPI's GPT-6 Luna docs[3].
GPT-6 Luna API name
The API model ID is gpt-6-luna. OpenAI lists that as both the model ID and the only snapshot, with the instruction "Use gpt-6-luna in your API requests."[2] reAPI uses the same string and treats it as a different model from gpt-5.6-luna and gpt-6-sol[3]. Azure error messages also mention a model version, gpt-6-luna-2026-09-22[10].
GPT-6 Luna API reasoning auto
There is no auto reasoning effort. OpenAI lists none, low, medium, high, xhigh and max for GPT-6 Luna, with medium as the default[2]. To get the model's default, omit reasoning_effort entirely. OpenAI's reasoning guide does use auto, but for other settings: reasoning summaries and the reasoning.context field[11].
GPT-6 Luna Azure
The most-cited Azure problem is not temperature. A Microsoft Q&A post from September 29, 2026 reports Foundry agents failing with "Unsupported parameter: 'reasoning.effort' is not supported with this model"[6]. A GitHub issue reproduces it on the Foundry project endpoint, where plain calls return 500 and effort returns 400, while the resource endpoint works with reasoning effort. The reporter's workaround is to call the resource endpoint, and the issue was still open when we checked on October 7, 2026[8].
GPT-6 Sol which effort
GPT-6 Sol takes the same six values as Luna, defaulting to medium[4][12]. OpenAI's general guidance is none for latency-critical work, low for tool use and drafting, medium for most workloads, high for hard debugging and planning, and xhigh only when evals justify the extra latency and cost[11]. Sol rejects temperature and top_p on reAPI just as Luna does[4].
Sending GPT-6 Luna requests that pass the first time
A clean GPT-6 Luna request has a model of gpt-6-luna, a messages array, a reasoning_effort you chose on purpose, and an output cap with room for reasoning. It has no temperature, top_p or penalty fields. If you came here to set temperature on the GPT-6 Luna API, the answer is to stop setting it: control cost and latency with effort, control shape with a strict JSON schema, and check what your framework adds by default. The same request shape works for GPT-6 Sol. Parameters are on the GPT-6 Luna docs and GPT-6 Sol docs, and current rates are on the GPT-6 Luna and GPT-6 Sol model pages.
References
- OpenAI. Using GPT-6. Retrieved October 2026 from developers.openai.com/api/docs/guides/latest-model
- OpenAI. GPT-6 Luna model page. Retrieved October 2026 from developers.openai.com/api/docs/models/gpt-6-luna
- reAPI. gpt-6-luna API documentation. Retrieved October 2026 from reapi.ai/docs/gpt-6-luna
- reAPI. gpt-6-sol API documentation. Retrieved October 2026 from reapi.ai/docs/gpt-6-sol
- Langflow on GitHub. Amazon Bedrock Converse: OpenAI GPT-6 Sol/Luna/Astra calls fail with 400 because Temperature and Top P are sent by default (#15349). Retrieved October 2026 from github.com/langflow-ai/langflow/issues/15349
- Microsoft Q&A. GPT-6-Luna agents fail with Unsupported parameter: 'reasoning.effort' error. Retrieved October 2026 from learn.microsoft.com/en-us/answers/questions/6018360
- Arize Phoenix on GitHub. Playground can't run OpenAI GPT-6 Sol/Luna/Astra on AWS Bedrock: default temperature=1 is always sent and rejected with 400 (#16430). Retrieved October 2026 from github.com/Arize-ai/phoenix/issues/16430
- Azure SDK for Python on GitHub. azure-ai-projects: gpt-6-luna returns 500 on project endpoint, works on resource endpoint (#49169). Retrieved October 2026 from github.com/Azure/azure-sdk-for-python/issues/49169
- redmine_ai_helper on GitHub. Chat fails with gpt-6 models (gpt-6-luna, gpt-6-sol): "Function tools with reasoning_effort are not supported" (#480). Retrieved October 2026 from github.com/haru/redmine_ai_helper/issues/480
- Microsoft Agent Framework on GitHub. Invalid parameter: 'text.format' of type 'json_schema' is not supported with model version gpt-6-luna-2026-09-22 (#8718). Retrieved October 2026 from github.com/microsoft/agent-framework/issues/8718
- OpenAI. Reasoning models. Retrieved October 2026 from developers.openai.com/api/docs/guides/reasoning
- OpenAI. GPT-6 Sol model page. Retrieved October 2026 from developers.openai.com/api/docs/models/gpt-6-sol
Further reading
- reAPI. GPT-6 Sol vs GPT-6 Luna. reapi.ai/blog/gpt-6-sol-vs-luna
- reAPI. GPT-6 Luna API pricing. reapi.ai/blog/gpt-6-luna-api-pricing
Author

Categories
More Posts
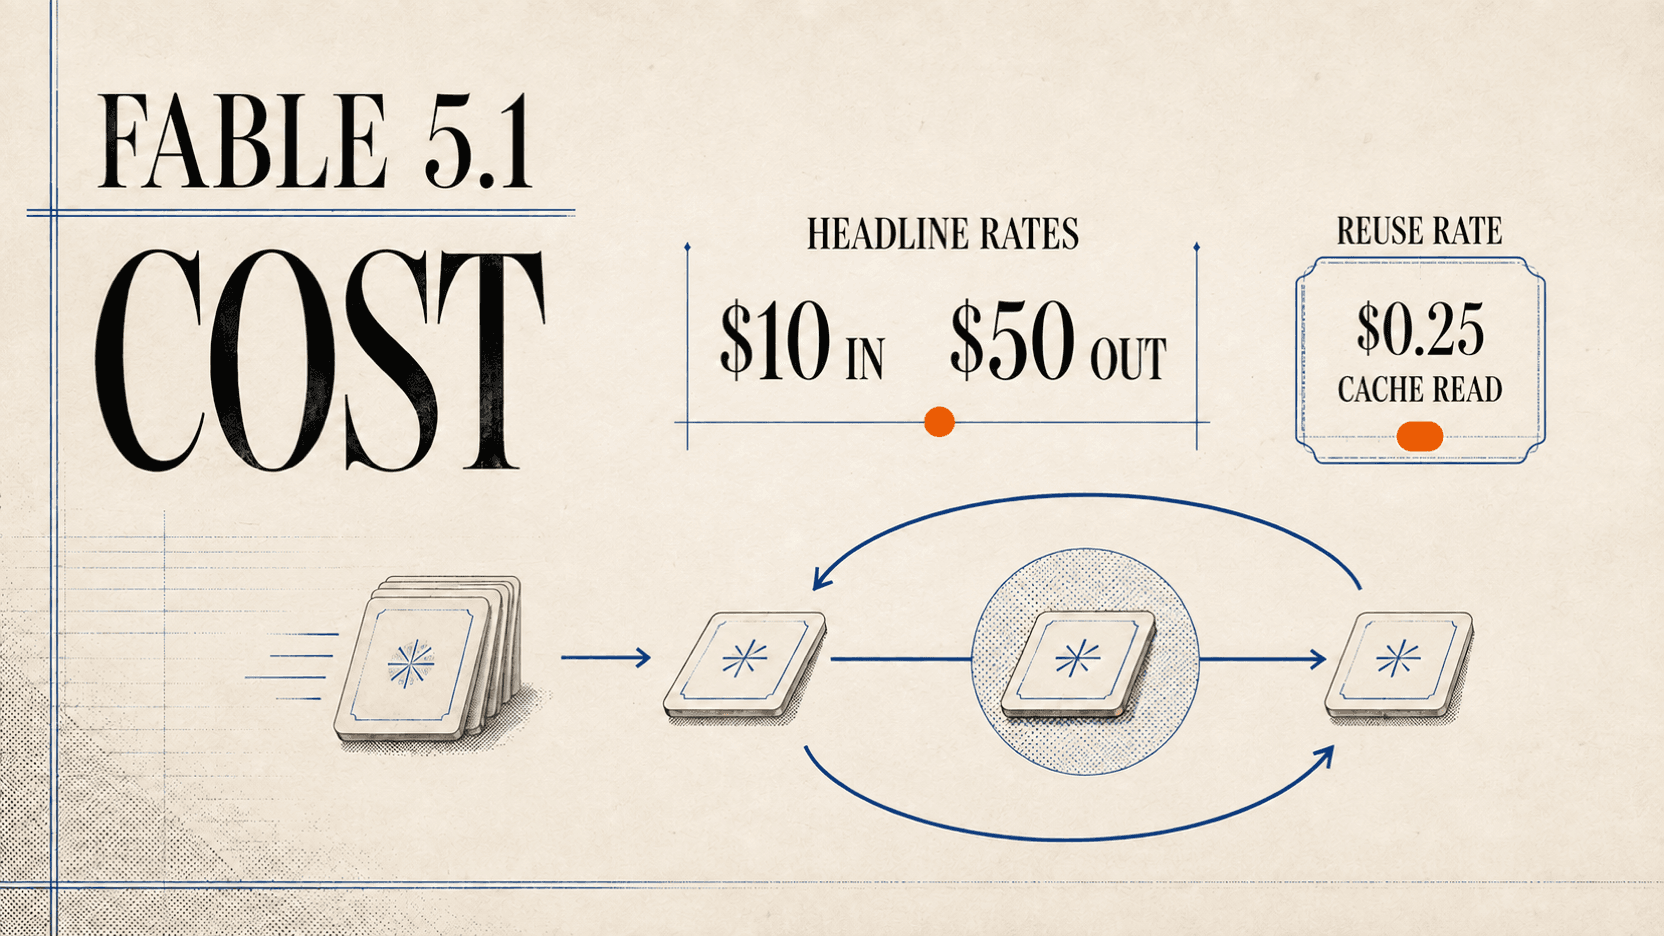
Is Claude Fable 5.1 Cheaper? The Cache Math Explained
Claude Fable 5.1 keeps Fable 5's $10/$50 rates but cuts cache reads to $0.25. Calculate the real task cost and avoid subscription-meter confusion.
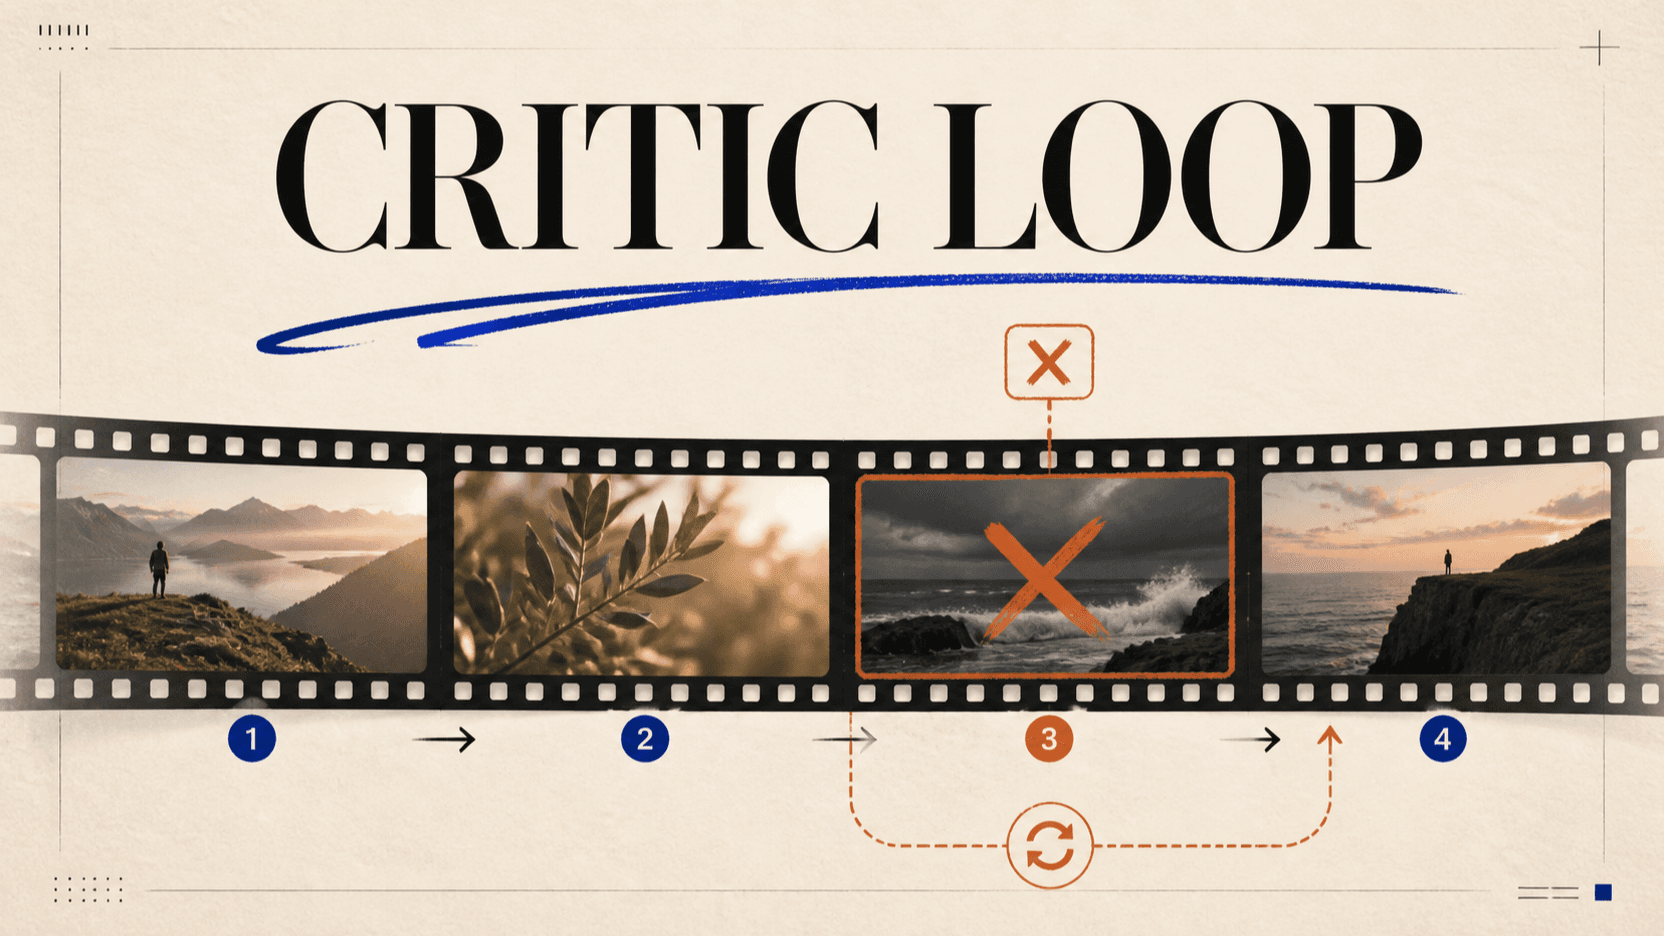
AI Video Agent Workflow: Build a Critic Loop for Reliable Video QA
Build an AI video agent critic loop with shot acceptance rules, repair scopes, retry budgets, and human review gates before bad generations reach the edit.
MiniMax H3 License: Territory, Revenue, and Commercial Use
MiniMax H3 is open-weight but not Apache or MIT. Read the territory exclusions, $20M revenue threshold, attribution rule, and self-hosting checklist.