Claude Haiku 5.5 vs Sonnet 5.5: Tools, Thinking, and Cost
Compare Claude Haiku 5.5 vs Sonnet 5.5 for tools, thinking, JSON, and token costs. See what reAPI tested and how to evaluate the models on your own workload.
Claude Haiku 5.5 and Claude Sonnet 5.5 both have a documented one-million-token context window and a 128,000-token standard output limit. Their controls differ: Haiku defaults to medium effort and permits forced tool selection, while Sonnet defaults to high effort and uses automatic tool selection[1][2].
That makes Haiku 5.5 vs Sonnet 5.5 a question about the workflow you need to run. This guide compares their documented request behavior, describes our small reAPI capability checks, and gives you a practical way to evaluate your own tasks. It does not rank coding quality or claim a latency advantage from a handful of requests.
TL;DR
- Both models accept text and images and return text, with the same documented context and ordinary output ceilings[1][2].
- Haiku can disable thinking at low, medium, or high effort and can force a named tool. These are useful control differences for a defined extraction or routing step[3].
- Sonnet offers between-tools thinking at low, medium, or high effort. It can skip initial thinking while retaining thinking between tool calls[4].
- Our October 9 checks observed structured JSON, tool-result continuation, document citations, streaming, and cache reads on both models. The API docs record the test scope[5][6].
- Compare current Haiku pricing and Sonnet pricing using a representative request. Official direct prices and reAPI prices are separate schedules[7].
Haiku 5.5 vs Sonnet 5.5: controls that change the workflow
A model switch can change more than the model ID. In a Haiku 5.5 vs Sonnet 5.5 migration, review thinking and tool selection before assuming an existing request has the same meaning.
| Documented property | Claude Haiku 5.5 | Claude Sonnet 5.5 |
|---|---|---|
| Model ID | claude-haiku-5-5 | claude-sonnet-5-5 |
| Context window | 1 million tokens | 1 million tokens |
| Standard output ceiling | 128,000 tokens, including thinking | 128,000 tokens, including thinking |
| Default effort | Medium | High |
| Effort choices | Low, medium, high, xhigh, max | Low, medium, high, xhigh, max |
| Skip initial thinking | Disabled mode at low, medium, or high | Between-tools mode at low, medium, or high |
| Forced tool selection | Supported | Use automatic selection |
| Release date | October 7, 2026 | September 28, 2026 |
The table summarizes Anthropic's model and migration documentation, checked October 9, 2026[1][2][3][4]. The limits are specifications, not a claim that our tests exercised maximum-size conversations.
For Haiku 5.5 vs Sonnet 5.5, equal context limits don't establish equal answer quality. A long request still needs a clear question and relevant evidence. Keep the input fixed when comparing the two models, and judge the answer against the same requirements.
Thinking settings in Haiku 5.5 vs Sonnet 5.5
Both models use adaptive thinking by default. Haiku's native default effort is medium; Sonnet's is high. Thinking consumes the output allowance, so a very small max_tokens budget can leave little room for a visible answer[3][4].
For a Haiku 5.5 vs Sonnet 5.5 evaluation, decide whether you're comparing each model's default experience or a common effort setting. Those are different experiments. Record the choice with your results so a later change to the prompt or effort doesn't look like an unexplained quality regression.
Haiku's documented thinking.type: "disabled" is available at low, medium, and high effort. Sonnet uses thinking.type: "between_tools" at those levels instead. The latter skips thinking before the initial response while permitting it between tool calls; it is not a general off switch[3][4].
This distinction matters if the first action should be a lookup. Your application may already know which record to retrieve and need the model to reason only after the result arrives. Test that sequence directly instead of using a single conversational answer as a proxy for the whole workflow.
Haiku 5.5 vs Sonnet 5.5 for tools and structured results
Haiku supports both any-tool selection and a named forced tool. Sonnet's migration guidance directs callers to automatic selection or no tools; our named-tool probe returned an upstream error for Sonnet[3][4][6].
In Haiku 5.5 vs Sonnet 5.5, this is a concrete integration difference. Consider a synthetic support workflow with one classification function. If every request must produce that function call, Haiku's forced selection is a feature to evaluate. If the application only needs a category record, structured JSON may be a simpler fit than treating classification as a tool.
Both models support structured JSON through output_config.format. A schema controls the output shape, while a tool definition describes a function your application may execute. Neither removes the need to check business facts: a correctly shaped date can still be the wrong date[8].
For a Haiku 5.5 vs Sonnet 5.5 tool comparison, keep execution in your application. Return the result with the matching tool-use ID and preserve the assistant's complete content, including signed thinking blocks. Flattening the previous reply to visible text loses state needed for a faithful conversation[3][4].
What our reAPI checks actually observed
We made 40 direct, bounded requests across the two models on October 9, 2026. They used synthetic text and tool fixtures, with no customer records or real tool actions. These were protocol and feature checks, not a coding benchmark or a load test. The individual model docs describe the observed features and untested scope[5][6].
| Check | Observed on both models |
|---|---|
| Basic text and system instruction | Expected synthetic marker returned |
| Streaming | Native message and content events returned |
| Structured JSON | Requested schema prevailed over a conflicting plain-text prompt |
| Strict client tool | Expected tool name and structured input returned |
| Tool-result continuation | Next response used the supplied synthetic tool result |
| Stop sequence | Stop reason matched; text after the marker was absent |
| Text-document citation | Answer included a citation block |
| Prompt cache | Cache-creation counters followed by cache-read counters |
For Haiku 5.5 vs Sonnet 5.5, these checks establish a useful starting set of application features. They don't tell you which model produces a better patch, how long a large PDF takes, or how either behaves under your production concurrency.
All five official effort values were accepted. We did not infer relative reasoning depth from that acceptance. Likewise, a response without a thinking block doesn't reveal every detail of the model's internal computation.
Native parameters pass through reAPI, including unknown extension fields. An HTTP 200 response is a normal accepted response, even if the upstream ignores a setting. Testing Haiku 5.5 vs Sonnet 5.5 therefore requires an observable outcome: a cache counter, the requested output shape, a stop reason, or a tool result that affects the next answer. Parameter acceptance and demonstrated behavior are separate facts[5][6].
Haiku 5.5 vs Sonnet 5.5 costs depend on the request
A Haiku 5.5 vs Sonnet 5.5 cost comparison needs input size, generated output, and cache use. Start with the current rates on the two model pages, then run a small representative sample and inspect its actual usage. Avoid multiplying only the visible answer length: thinking is part of output usage[3][4].
Anthropic's direct Haiku price schedule changes above 100,000 prompt tokens, with cached input included in the threshold. Sonnet's documented one-million-token window has no corresponding long-context premium in the current direct schedule. These conditions belong to Anthropic's pricing; do not silently apply them to a different service's quote[7].
Caching is worth evaluating when requests repeatedly share a stable prefix. Both models document a 512-token minimum cacheable prefix and support five-minute and one-hour cache lifetimes. A cache setting in an accepted request is not evidence of a hit; inspect creation and read counters[9].
For Haiku 5.5 vs Sonnet 5.5, keep the cache conditions comparable. Mixing a warm repeated prompt on one model with a new prompt on the other makes the cost comparison difficult to interpret. Record whether you're measuring a first request or repeated use, and don't describe one sample as an account-wide saving.
Build a small evaluation around an actual decision
Use a workload you can grade without relying on another model's opinion. For extraction, prepare source notes with known fields and deliberate omissions. For code review, use a defect with a failing test. For a research brief, prepare a source set with at least one unresolved question that the answer should preserve.
Haiku 5.5 vs Sonnet 5.5 becomes easier to assess when the failure criteria are explicit. An extraction answer fails if it invents a missing date. A proposed patch fails if it changes unrelated behavior. A research answer fails if its cited passage doesn't support the claim. These are suggested evaluation rules, not claims about either model's observed performance.
Run Haiku 5.5 vs Sonnet 5.5 with the same inputs, recorded effort, and output budget. Keep the returned content, usage, and stop reason. If you add a tool, test the complete loop: a correct initial call is only one step, and the useful result arrives after the application returns data.
Use the Haiku Messages examples and Sonnet Messages examples to keep the transport format consistent. The Claude context guide offers additional background; check exact model documentation for version-specific limits.
Haiku 5.5 vs Sonnet 5.5 FAQ
Is Haiku 5.5 better than Sonnet 5.5?
There is no universal winner established by these checks. Haiku offers forced tool selection and a disabled-thinking mode; Sonnet has different default effort and between-tools behavior. Compare the result against your workload's requirements before choosing[3][4].
Is the context window the same in Haiku 5.5 vs Sonnet 5.5?
Yes. Both document one million tokens of context and 128,000 tokens of standard output, including thinking. Equal limits do not demonstrate equal retrieval or reasoning quality on a long input[1][2].
Which one should I use for coding?
Evaluate both on a change with a known acceptance test. Our Haiku 5.5 vs Sonnet 5.5 checks tested API features, not coding quality. The Sonnet page includes a code-review starting prompt; adapt it to the modules and constraints in your project.
Do both Haiku 5.5 and Sonnet 5.5 support structured JSON?
Yes. Both support output_config.format with a JSON schema. Our small tests observed schema-conforming output despite a conflicting plain-text instruction. Evaluate your actual schemas separately, including missing values and any domain-specific validation[5][6].
Can I use document citations with JSON output?
Anthropic documents citations and structured JSON as incompatible in the same request. Choose a cited narrative when source review matters, or structured JSON when your application needs fields; design a separate verification step if you need both outcomes[8].
Are Claude subscriptions and reAPI calls billed together?
No. Calls made with a reAPI key use your reAPI account's billing. Check the model page for current token rates. A separate Claude subscription does not pay for those requests[5][6].
Choose with a result you can check
Begin your Haiku 5.5 vs Sonnet 5.5 comparison with a bounded extraction task, a reproducible code issue, or a source-backed decision. Keep the prompt and evaluation criteria fixed, then inspect correctness and actual usage before changing settings.
Documented controls help you select a Haiku 5.5 vs Sonnet 5.5 candidate; the complete workflow tells you whether it fits. Open Claude Haiku 5.5 or Claude Sonnet 5.5, try a representative task, and use the linked Messages examples when you are ready to integrate.
References
- Anthropic. Claude Haiku 5.5 overview. Retrieved October 9, 2026 from platform.claude.com/docs/en/models/haiku-5-5/overview.
- Anthropic. Claude Sonnet 5.5 overview. Retrieved October 9, 2026 from platform.claude.com/docs/en/models/sonnet-5-5/overview.
- Anthropic. Haiku 5.5 migration guidance. Retrieved October 9, 2026 from platform.claude.com/docs/en/models/haiku-5-5/migration-guide.
- Anthropic. Sonnet 5.5 migration guidance. Retrieved October 9, 2026 from platform.claude.com/docs/en/models/sonnet-5-5/migration-guide.
- reAPI. Haiku 5.5 API documentation and observed capabilities. October 9, 2026. reapi.ai/docs/claude-haiku-5-5.
- reAPI. Sonnet 5.5 API documentation and observed capabilities. October 9, 2026. reapi.ai/docs/claude-sonnet-5-5.
- Anthropic. Pricing. Retrieved October 9, 2026 from platform.claude.com/docs/en/about-claude/pricing.
- Anthropic. Structured outputs. Retrieved October 9, 2026 from platform.claude.com/docs/en/build-with-claude/structured-outputs.
- Anthropic. Prompt caching. Retrieved October 9, 2026 from platform.claude.com/docs/en/build-with-claude/prompt-caching.
Author

Categories
More Posts
Cheapest Seedance 2.5 in 2026: Compare Real API Costs
Find the cheapest Seedance 2.5 option for your resolution: compare current API rates, 10-second costs, reference-video billing, and subscription credit limits.
GPT-6 Luna API Set Temperature: Why It Returns 400 and What to Send
Trying to set temperature on the GPT-6 Luna API? Why GPT-6 Luna and Sol return 400 for temperature and top_p, the exact model ID, and a fixed request.
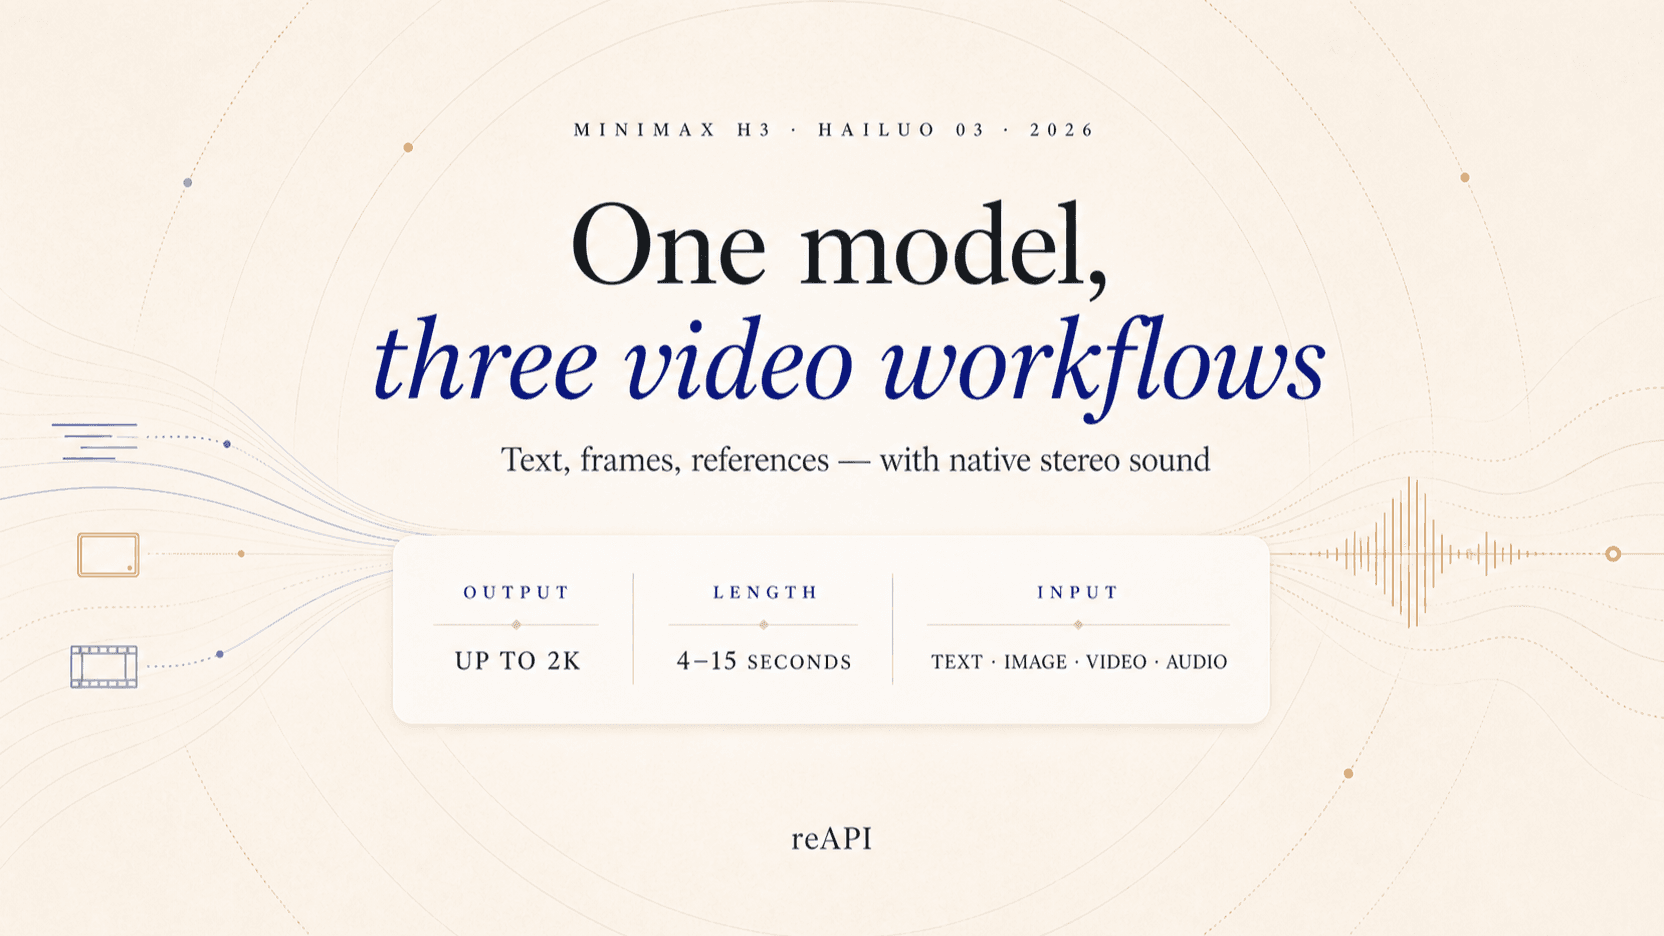
Hailuo H3 Explained: MiniMax H3 Specs, Pricing, API, and Limits (2026)
Learn how Hailuo H3, MiniMax H3, and Hailuo 03 relate, with verified 2K video specs, native audio, pricing, API limits, and integration code.